Bright English
Work on an existing English‑learning app built around spaced repetition: 20+ locales, RTL support, light and dark themes, iOS/Android.
Product Context
Bright English is an English‑learning app built around vocabulary growth and spaced repetition. Users learn new words, meet them again in different exercises, and gradually turn passive recognition into understanding and use.
When I joined the team, the app already existed. Every new feature had to fit into the existing UI: 20+ locales, RTL languages, light and dark themes, iOS and Android, existing training logic, analytics, content infrastructure, and user expectations.
Feature 1. Dialogues
Bright already handled vocabulary and repetition well, but speaking practice was still a separate pain point. A user could know words, complete exercises, and still freeze when they had to answer with a real phrase in a specific situation.
Hypothesis: if users get short role‑play dialogues with AI characters, goals, and gentle feedback, speaking practice will feel less intimidating and more practical.
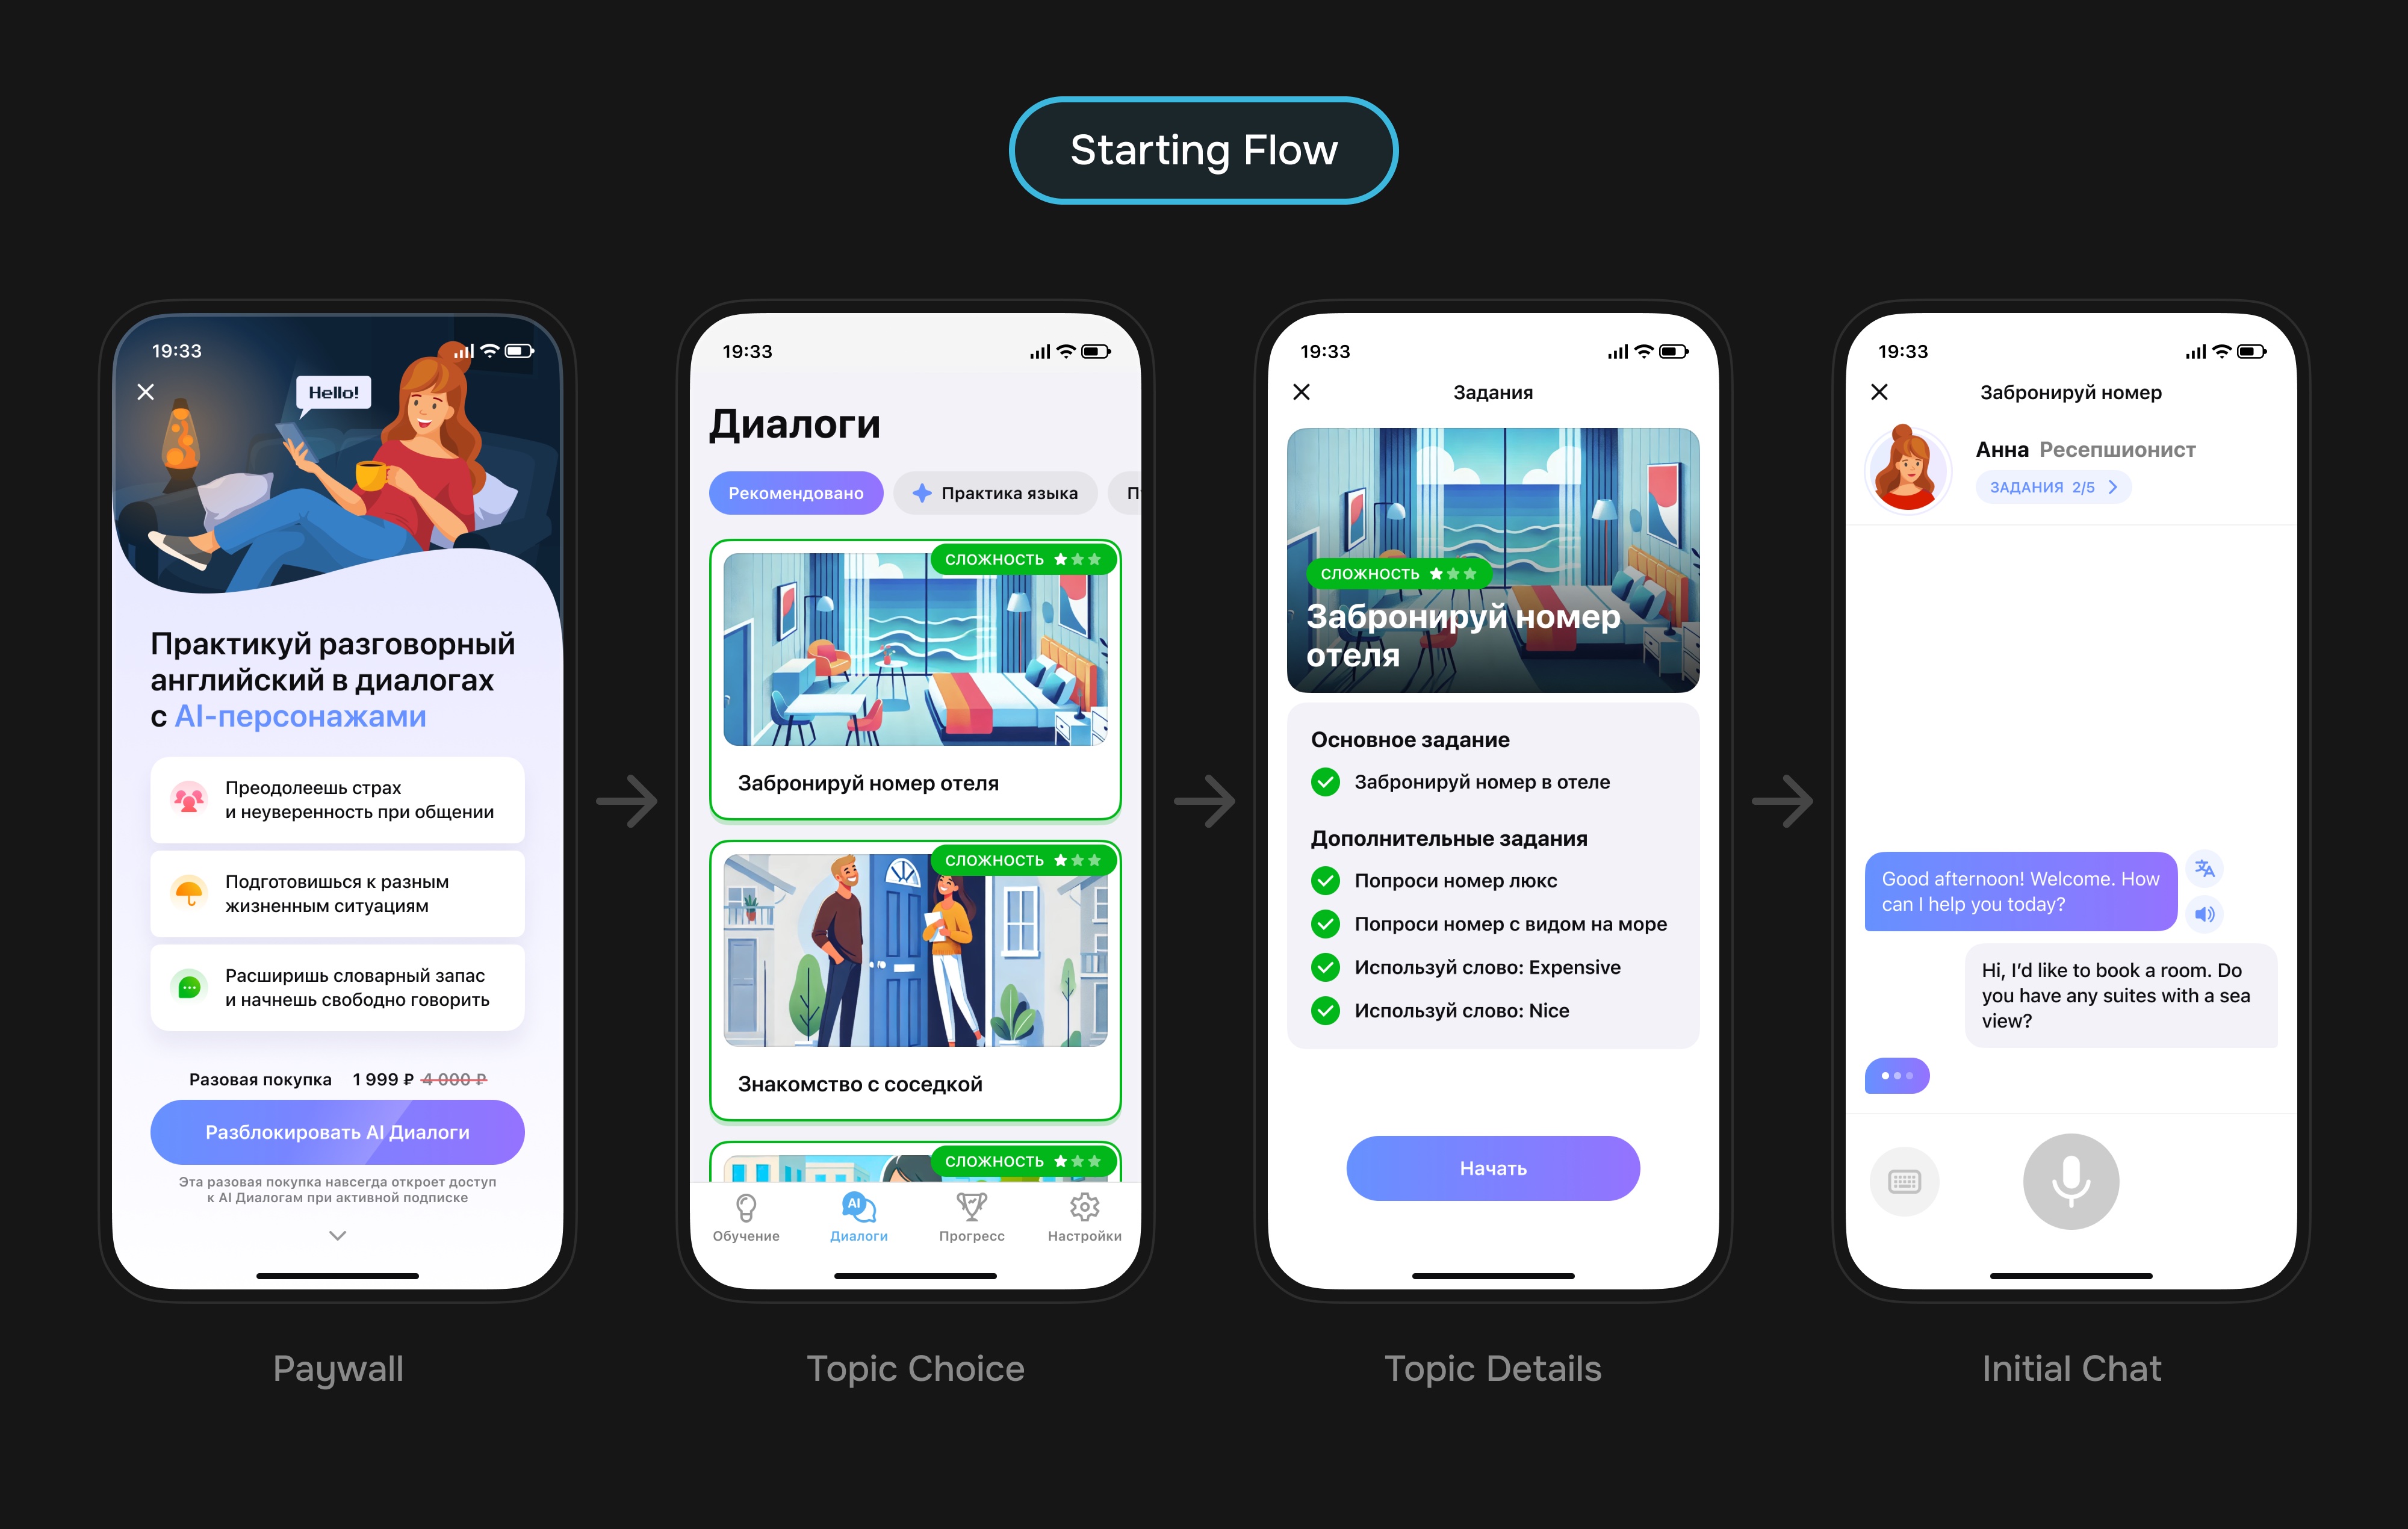
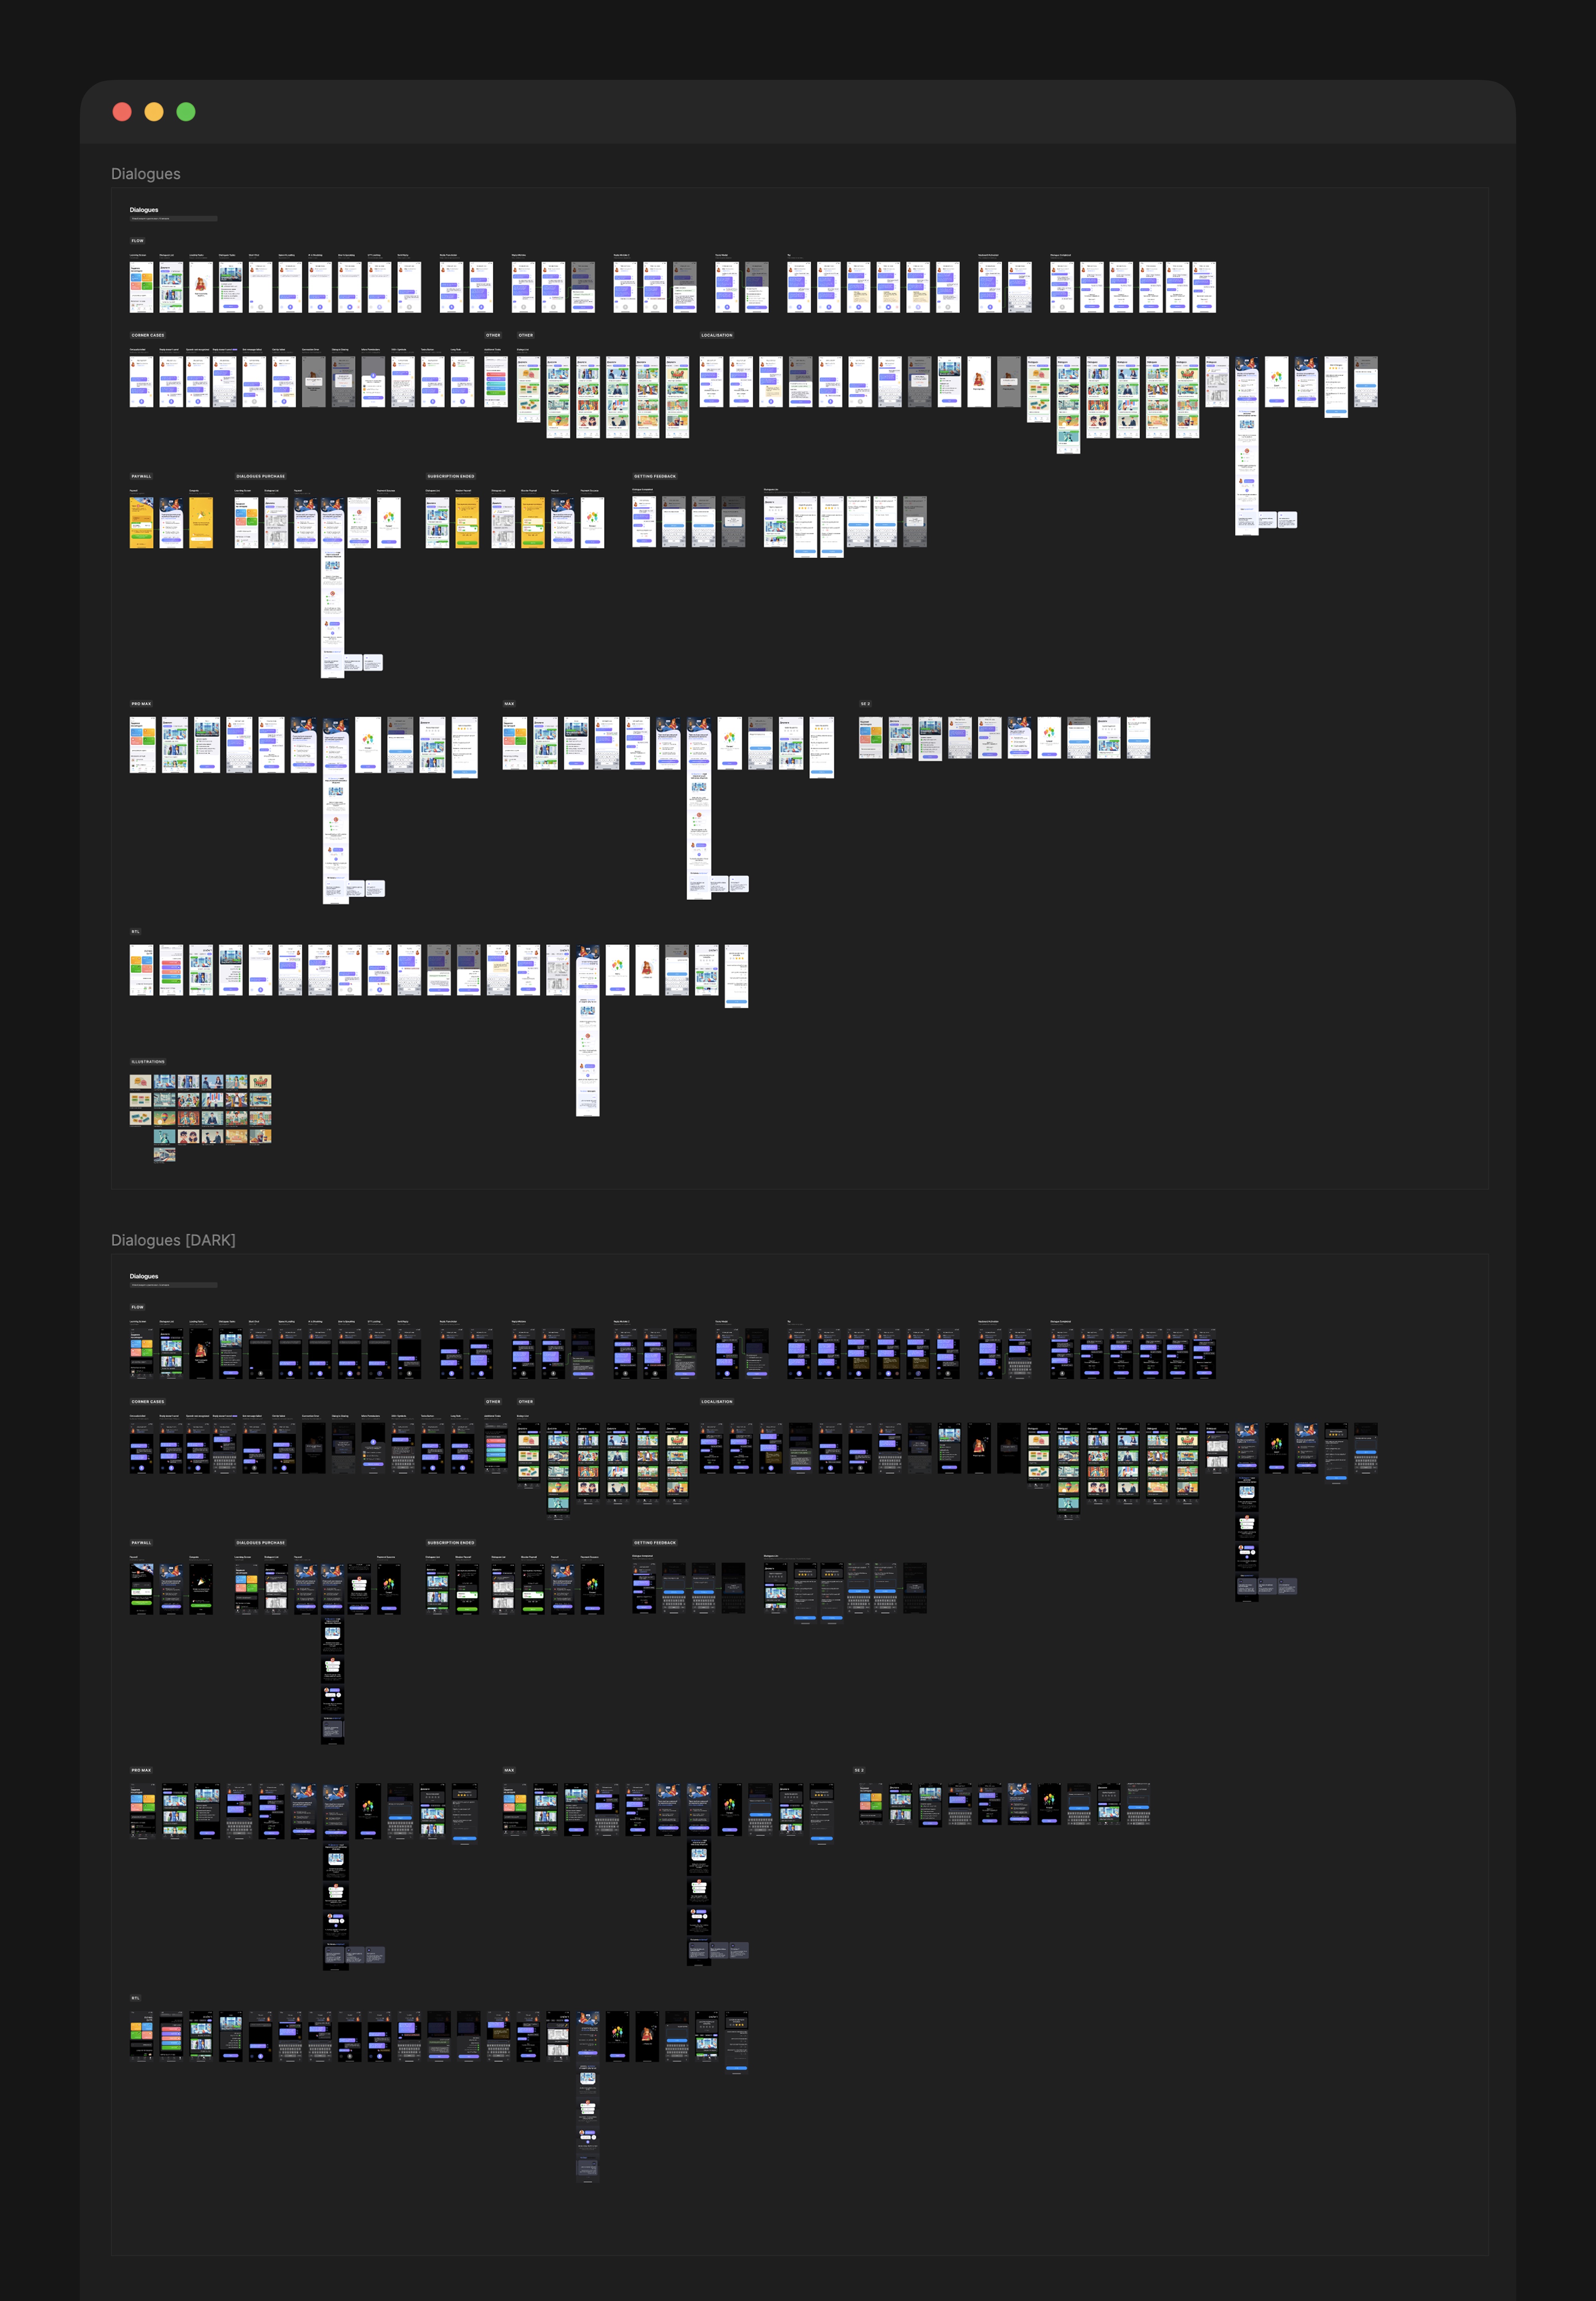
The feature was not just a chat screen. It had to become a new learning surface inside the app: a bottom‑tab entry point, a scenario catalog, a briefing screen, and a task‑based conversation with hints, translation, voice input, and error checking. The first version launched as a product feature for new users in supported locales, and later we separately tested an AI Dialogues upsell.
Scenarios and Catalog
The catalog had to feel like part of a learning product, not a list of random chats. Scenarios were grouped by real‑life topics: travel, communication, work, city life, food and drinks, plus free speaking practice. Cards had difficulty, illustration, completion state, and sorting rules.
| Part | How It Worked | Why |
|---|---|---|
| Entry point | A Dialogues button in the bottom navigation and a first‑entry onboarding overlay | Make the new format visible without breaking the familiar app structure |
| Catalog | Topic‑based scenarios, recommendations based on user interests, completed cards moved lower | Help users pick a situation quickly and preserve a sense of progress |
| Briefing | Before the chat, users saw their role, main goal, and additional tasks | Turn open‑ended conversation into a clear learning mission |
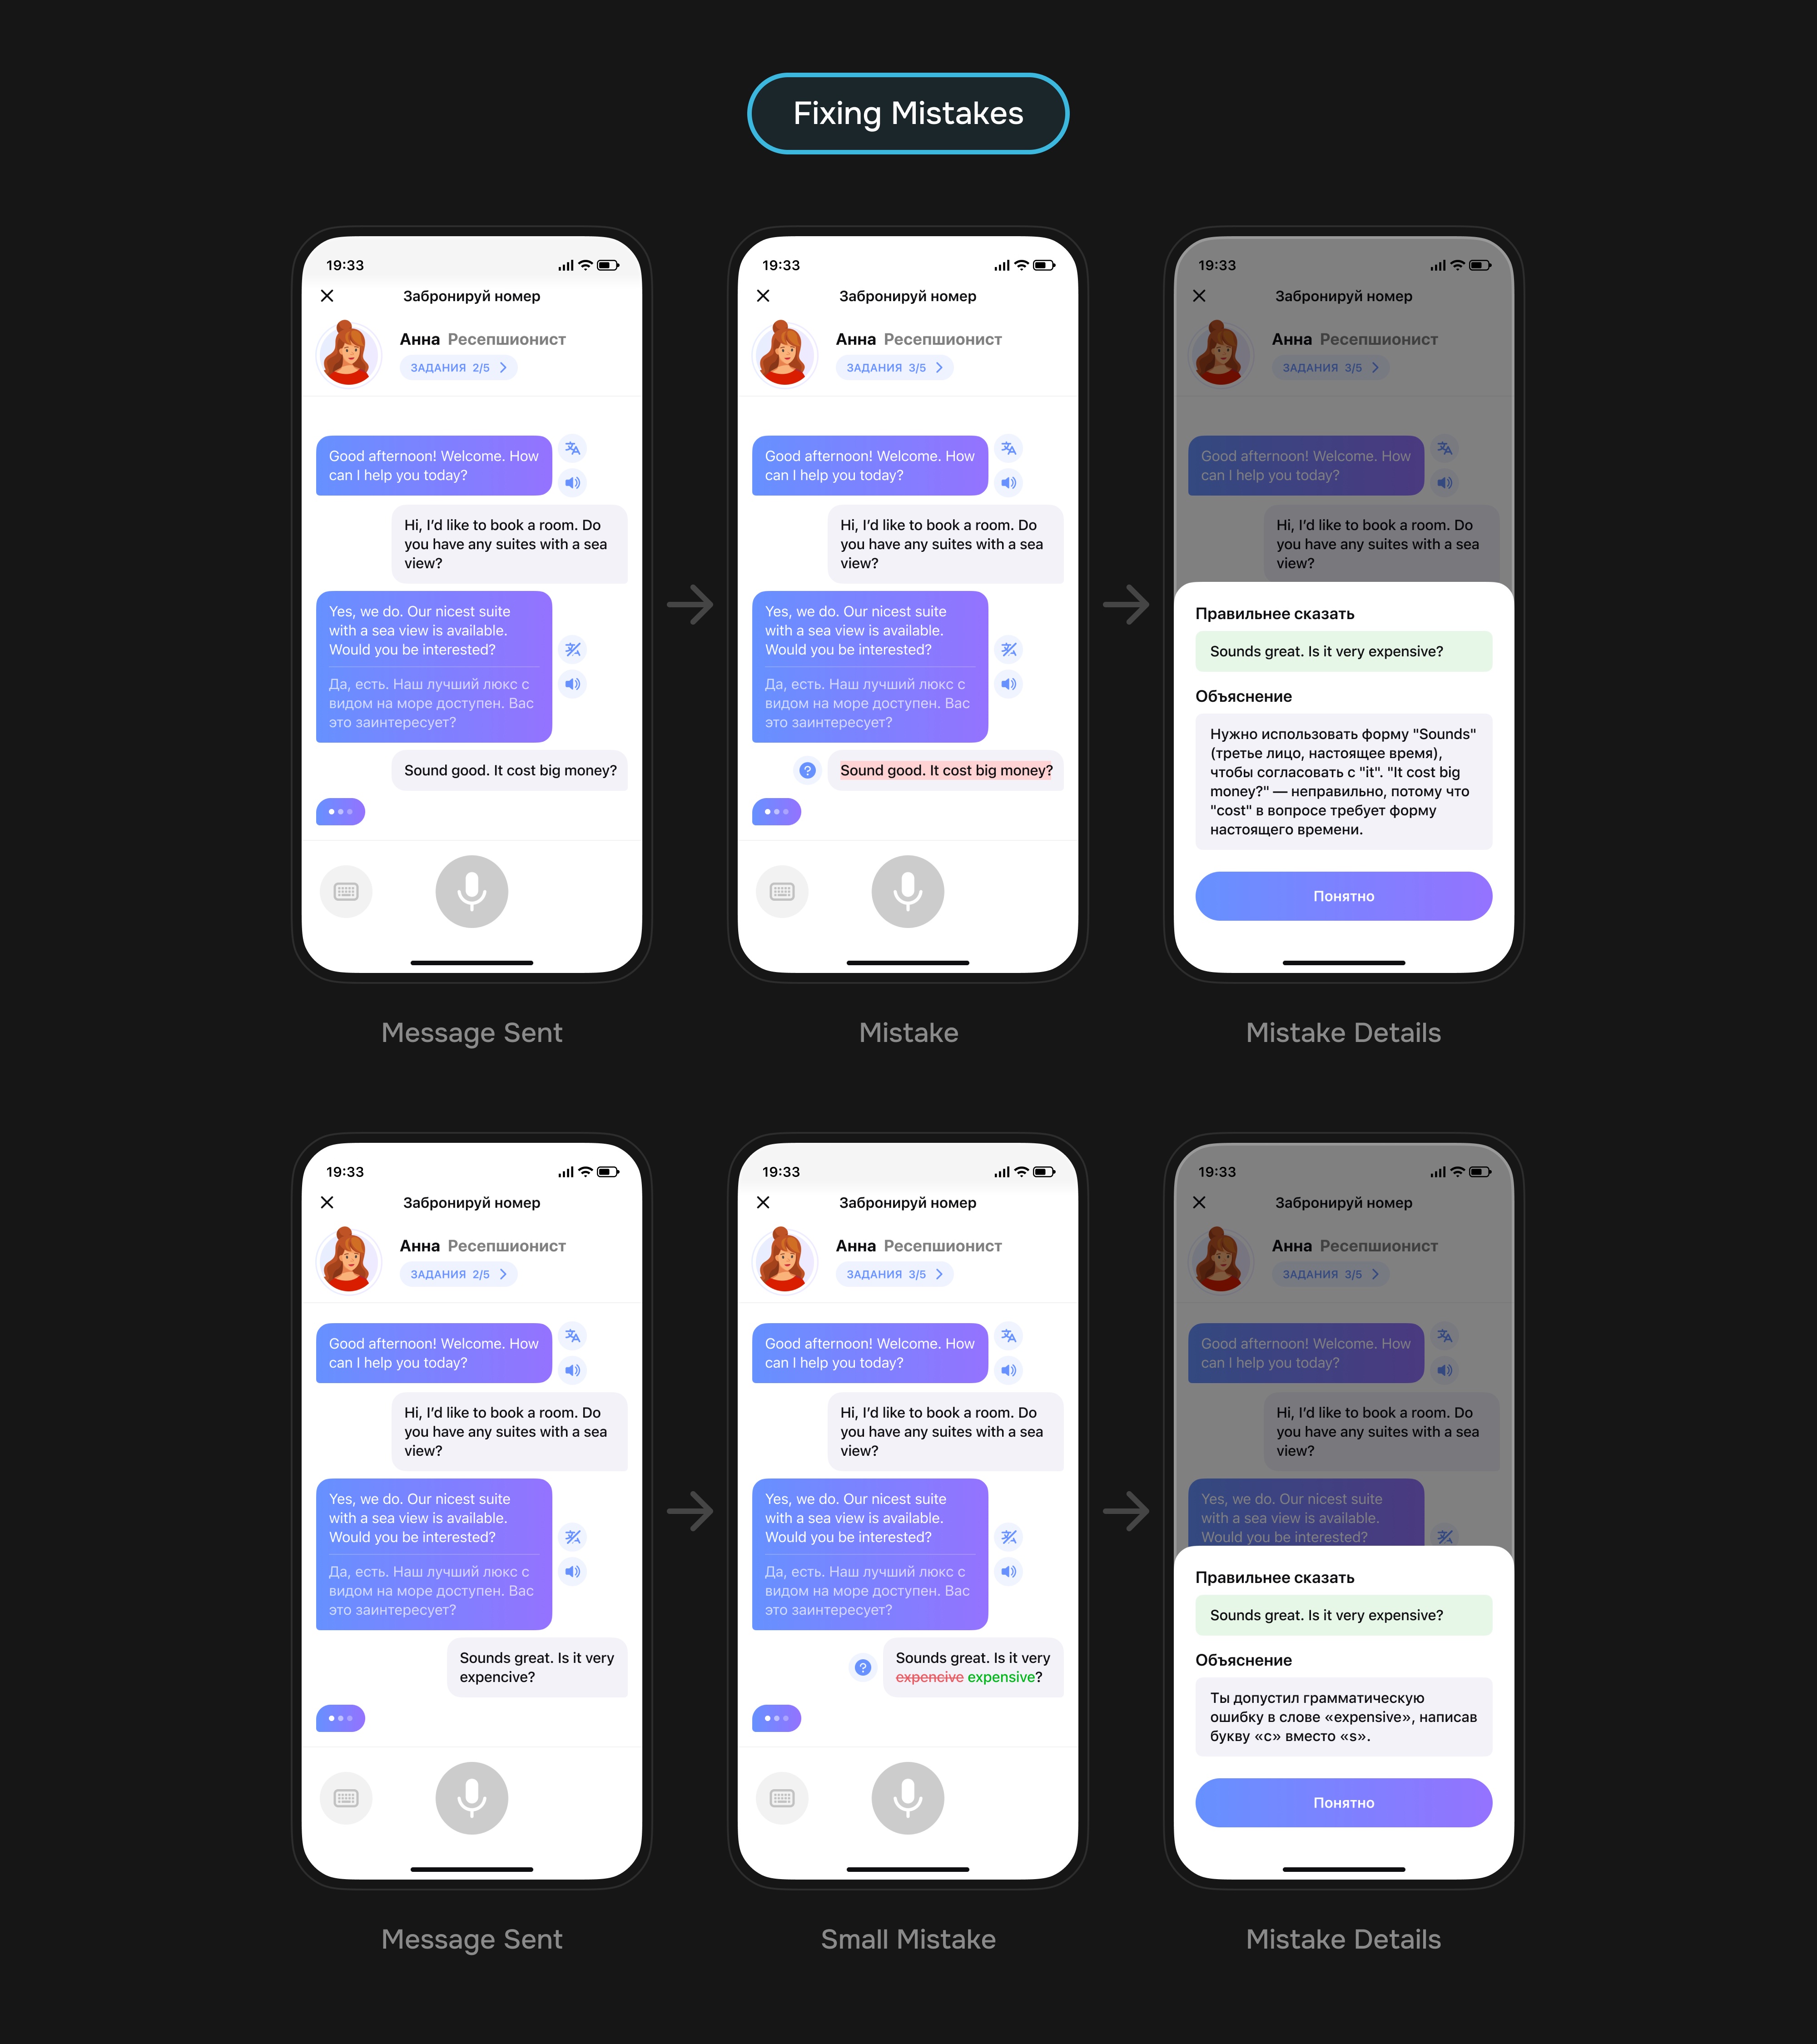
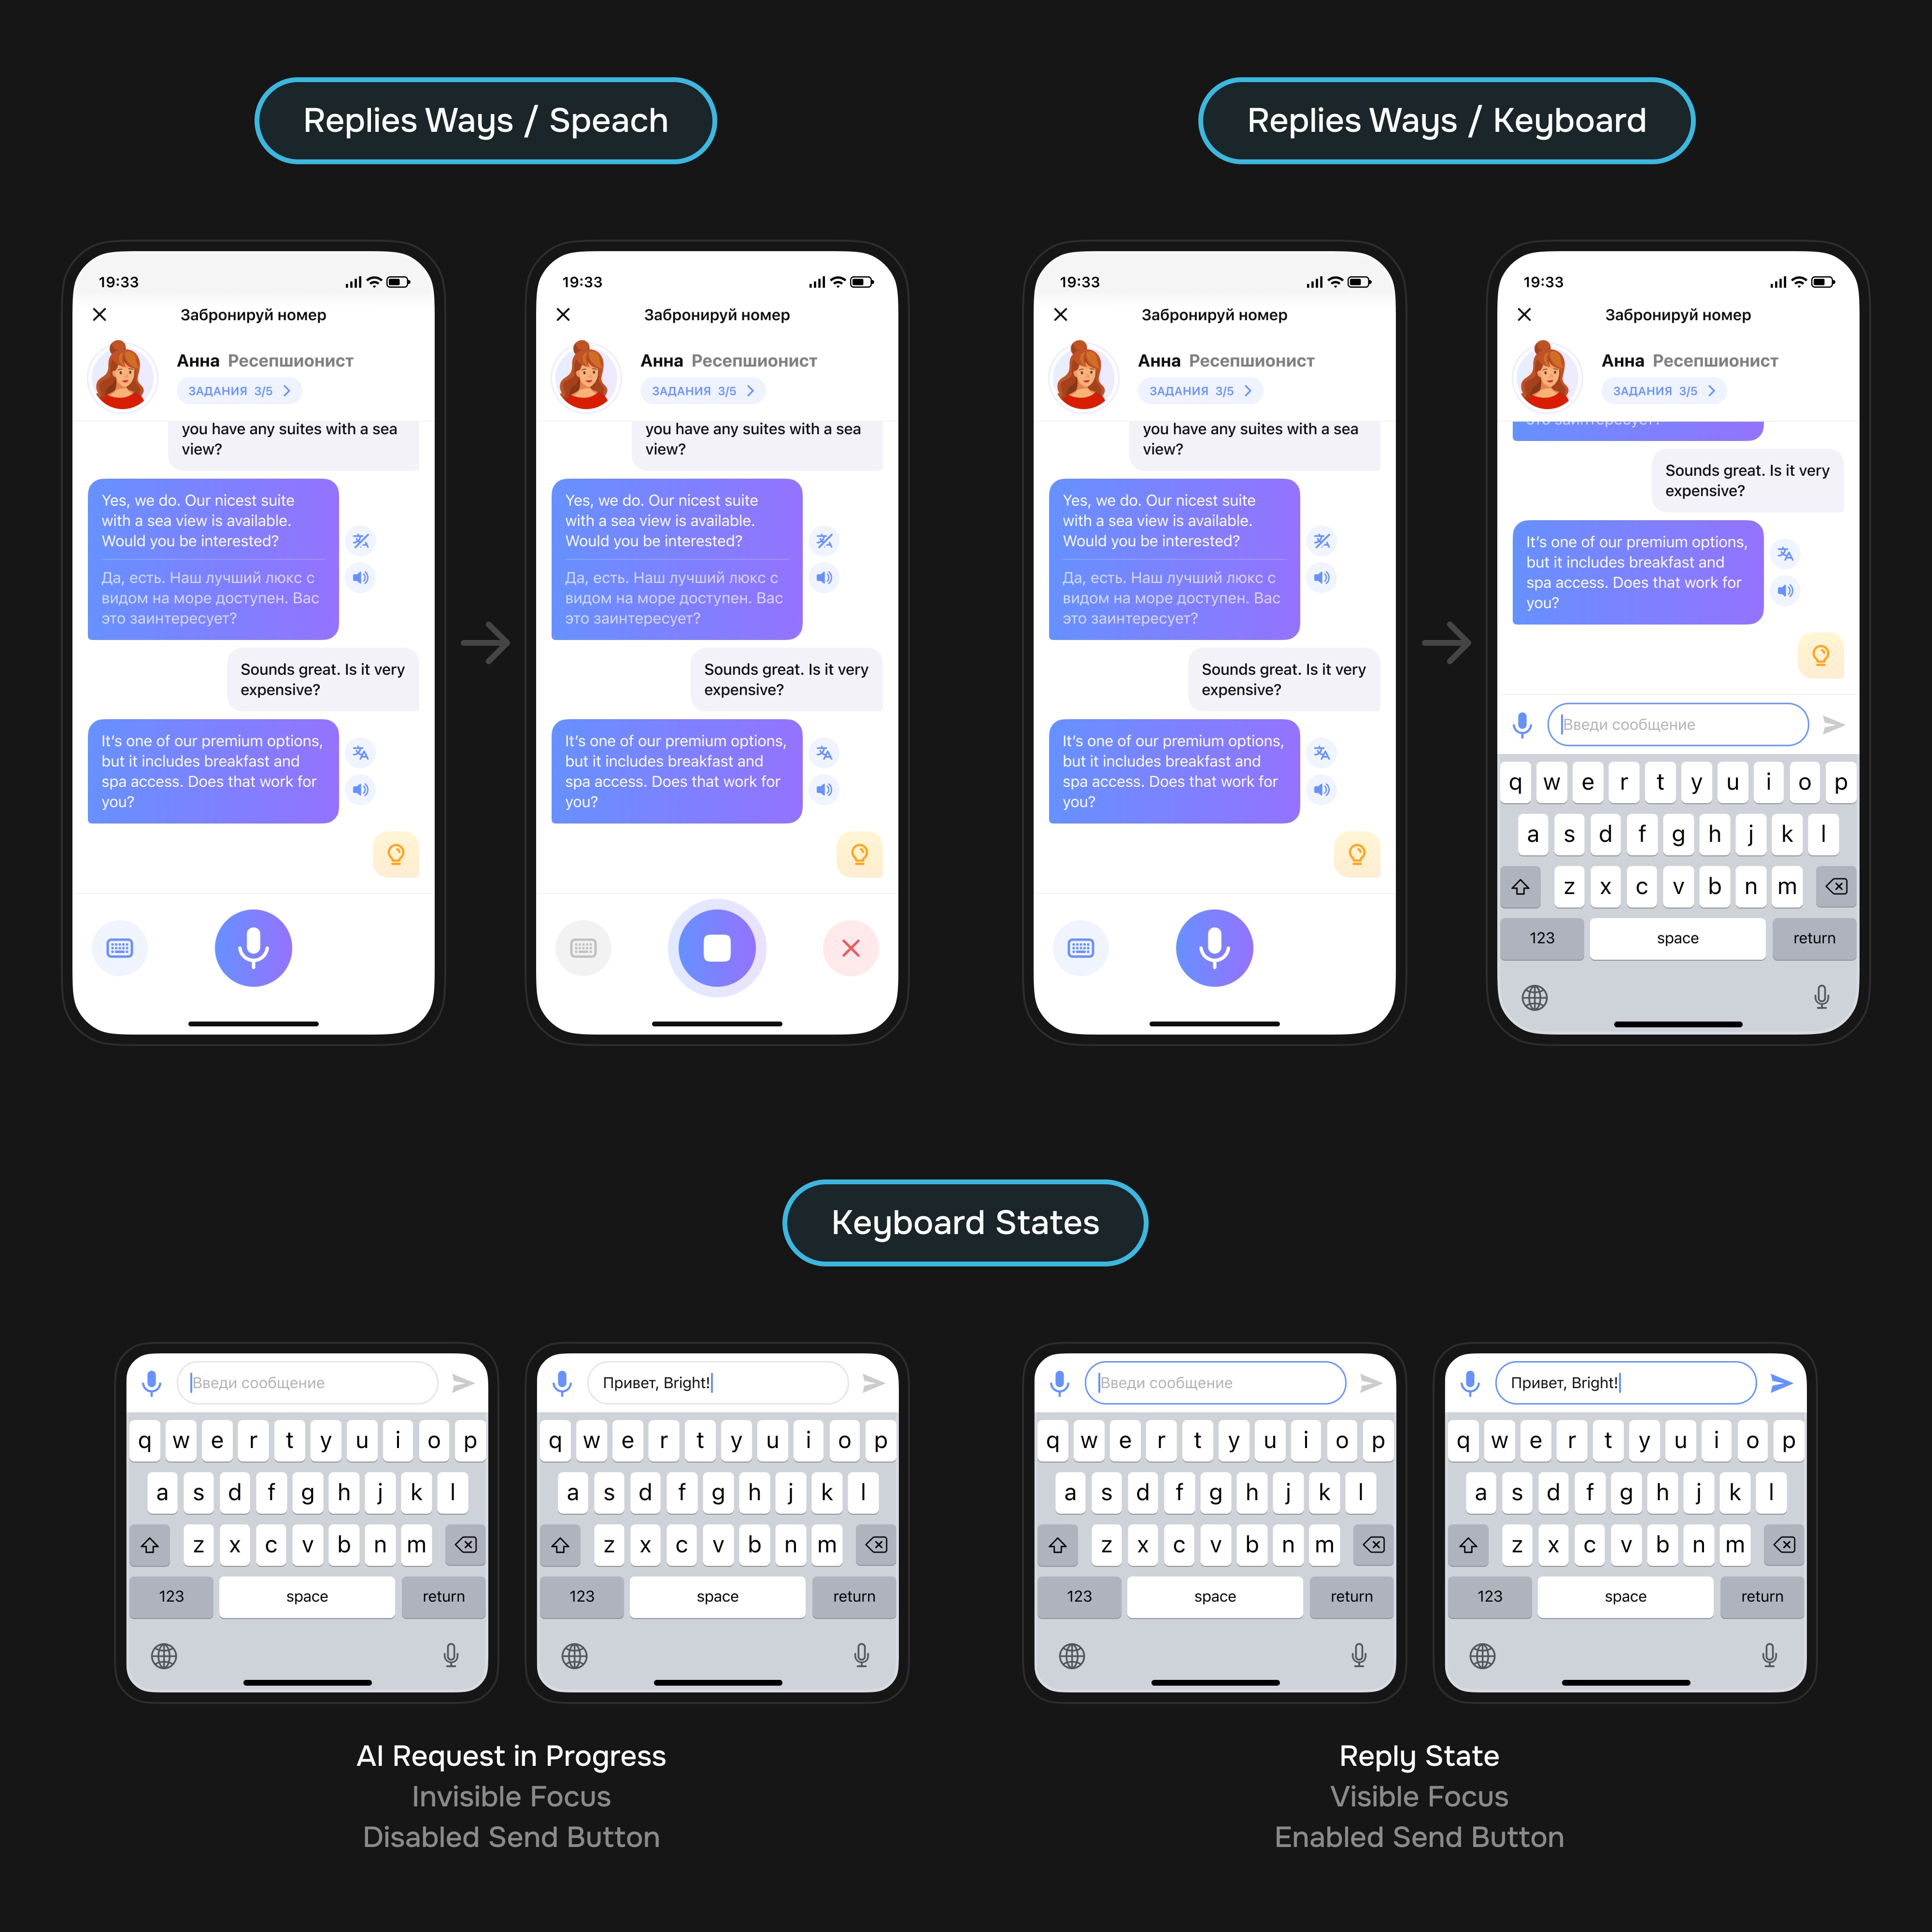
| Dialogue | During the conversation, mistakes were highlighted, and users had reply hints, translation, audio, and a choice between voice input and keyboard | Make the chat a learning exercise where users could make mistakes and keep going without stress |
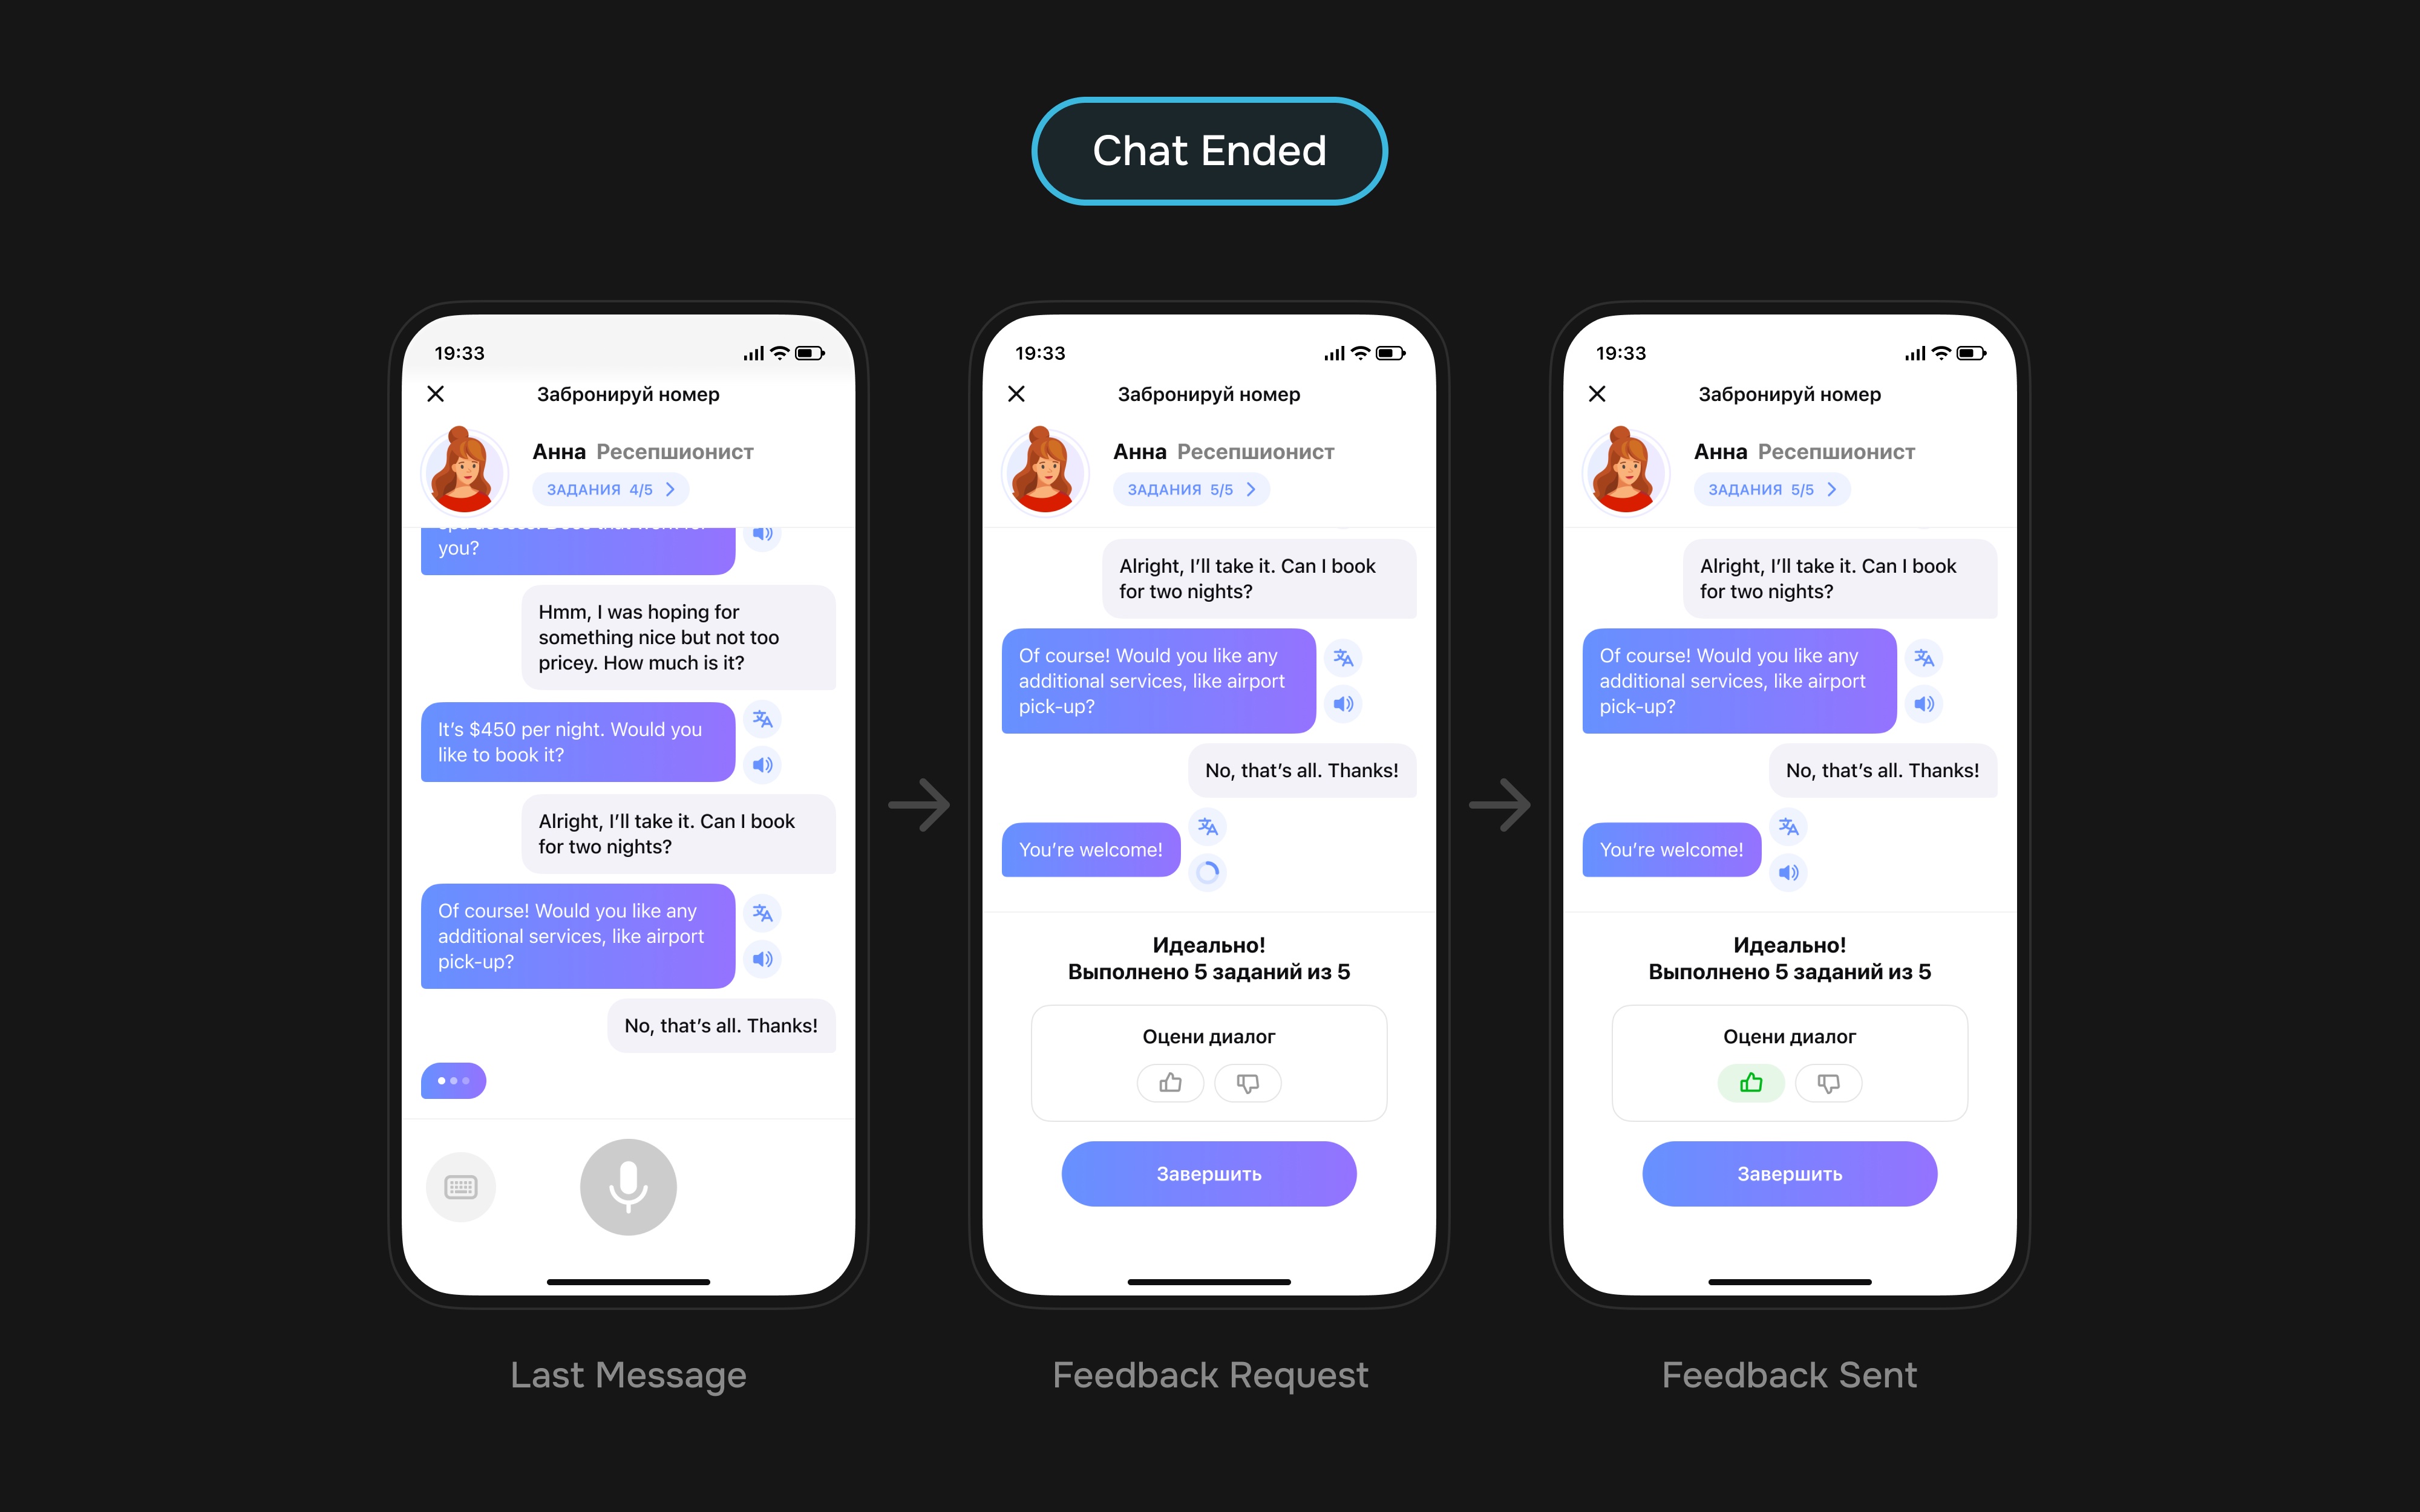
| Completion | At the end, users saw completed tasks, a dialogue rating, and a return‑to‑catalog action | Close the session as a complete exercise, not an abandoned chat |
In‑Conversation Support
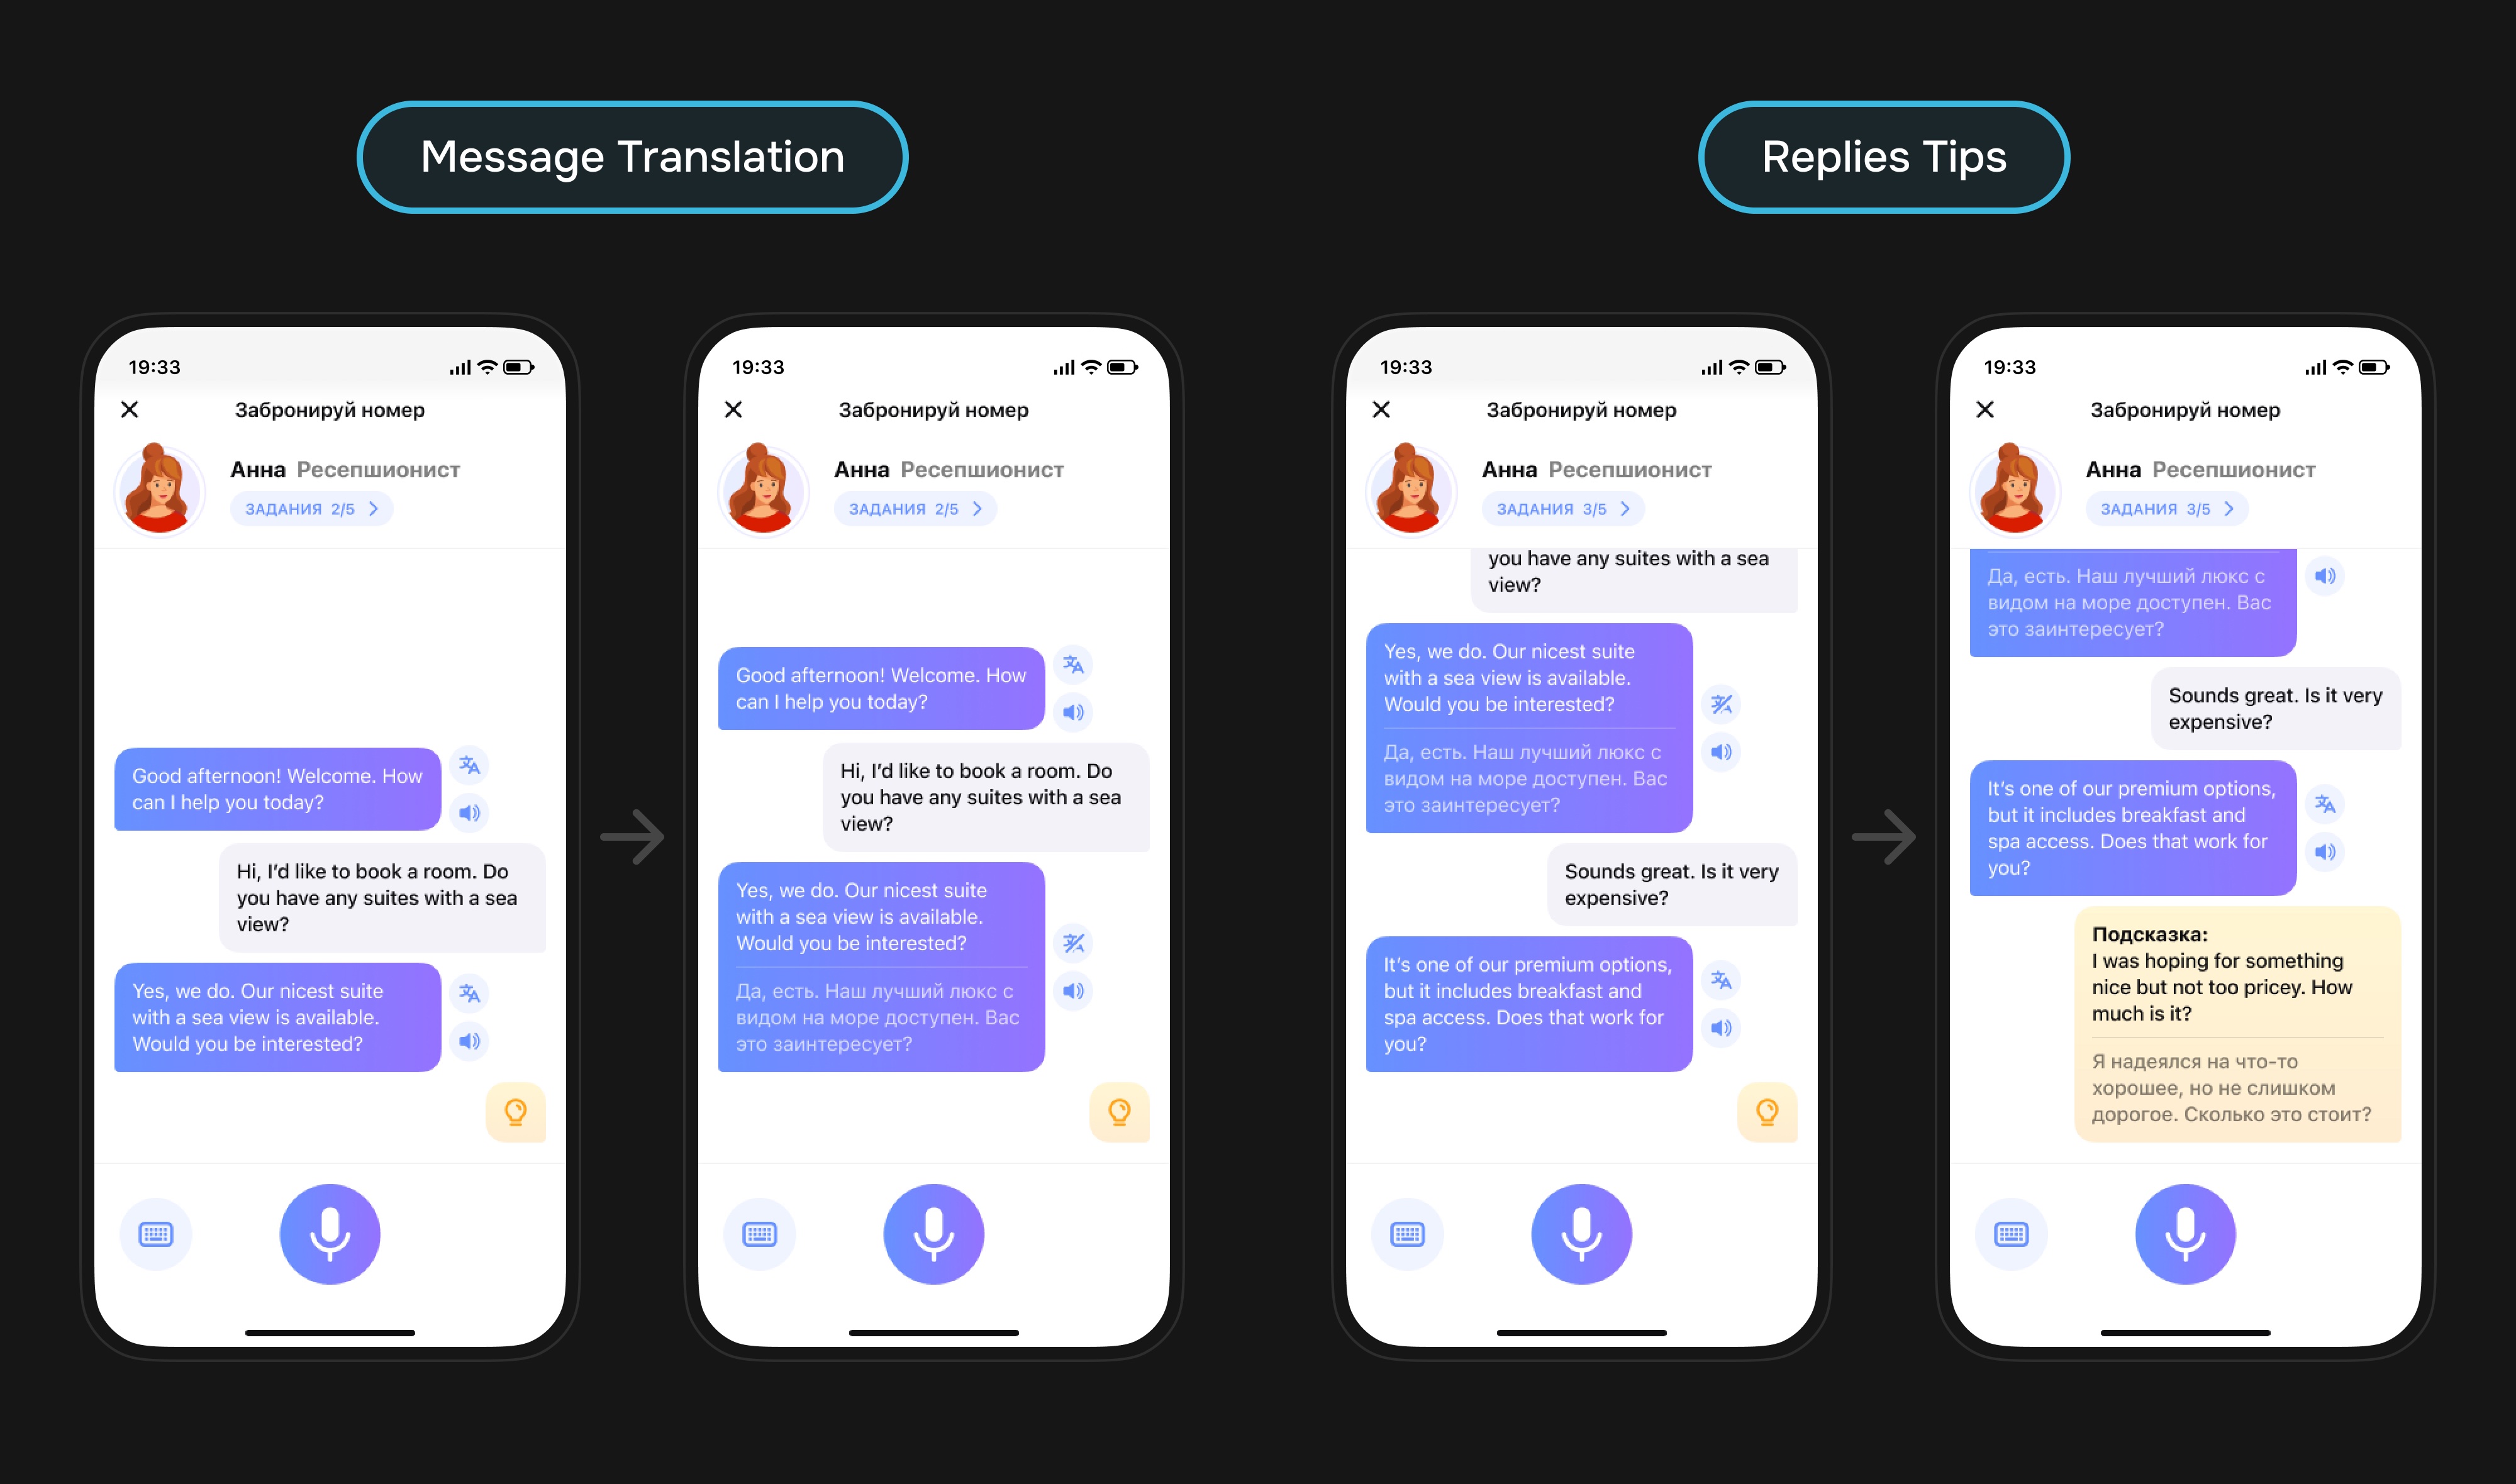
The main risk was that chat can easily become stressful: users do not know what to say, fear making mistakes, or do not understand the AI character's message. So the message itself got a learning layer around it: translation, audio, reply hints, voice input, and gentle error explanations.
Upsell and A/B Test
After launching the feature itself, we separately tested whether users were willing to pay for AI Dialogues as an extra value layer. The A/B test ran from July 2 to July 17, 2025 in version 2.7.14: in group A, Dialogues were included in the regular subscription; in group B, they were unlocked through a separate IAP.
Financially, the upsell group looked stronger: first‑year LTV grew by 7.9%, while the average regular subscription check barely changed. But the test also showed the cost of the decision: overall trial‑to‑subscription conversion stayed at 25.5% in both groups, while fast trial cancellations within the first 3 hours grew from 21.1% to 25.7%. The separate paywall increased motivation among interested users, but could scare off a more anxious part of the audience.
Outcome
Dialogues added a new practice layer to Bright: not word repetition and not choosing the right answer, but a short simulation of a real‑life situation. To users it looked like a conversation with a character, while underneath it had a learning structure: role, goal, additional tasks, translation, hints, corrections, and final completion.
For me, this feature was about carefully turning AI into a learning tool: not giving users an empty input field, but building a scenario, support system, and clear product mechanics around it.
Feature 2. Words in Sentences
The problem was that users could successfully complete isolated word exercises, but that did not always translate into understanding a word inside a real sentence. Language learning needs context: a word should appear not only as a word‑to‑translation card, but as part of meaning.
Hypothesis: if users practice already learned words inside sentences, the exercise will become more educationally valuable and closer to real language use.
The new training had to appear as a separate card on the home screen (the home screen is covered separately in the second feature). Inside it, users no longer worked with isolated words, but with sentences containing the words they had learned: inserting one or several words, assembling a sentence, working with audio, and getting an explanation after an error.
Starting Point
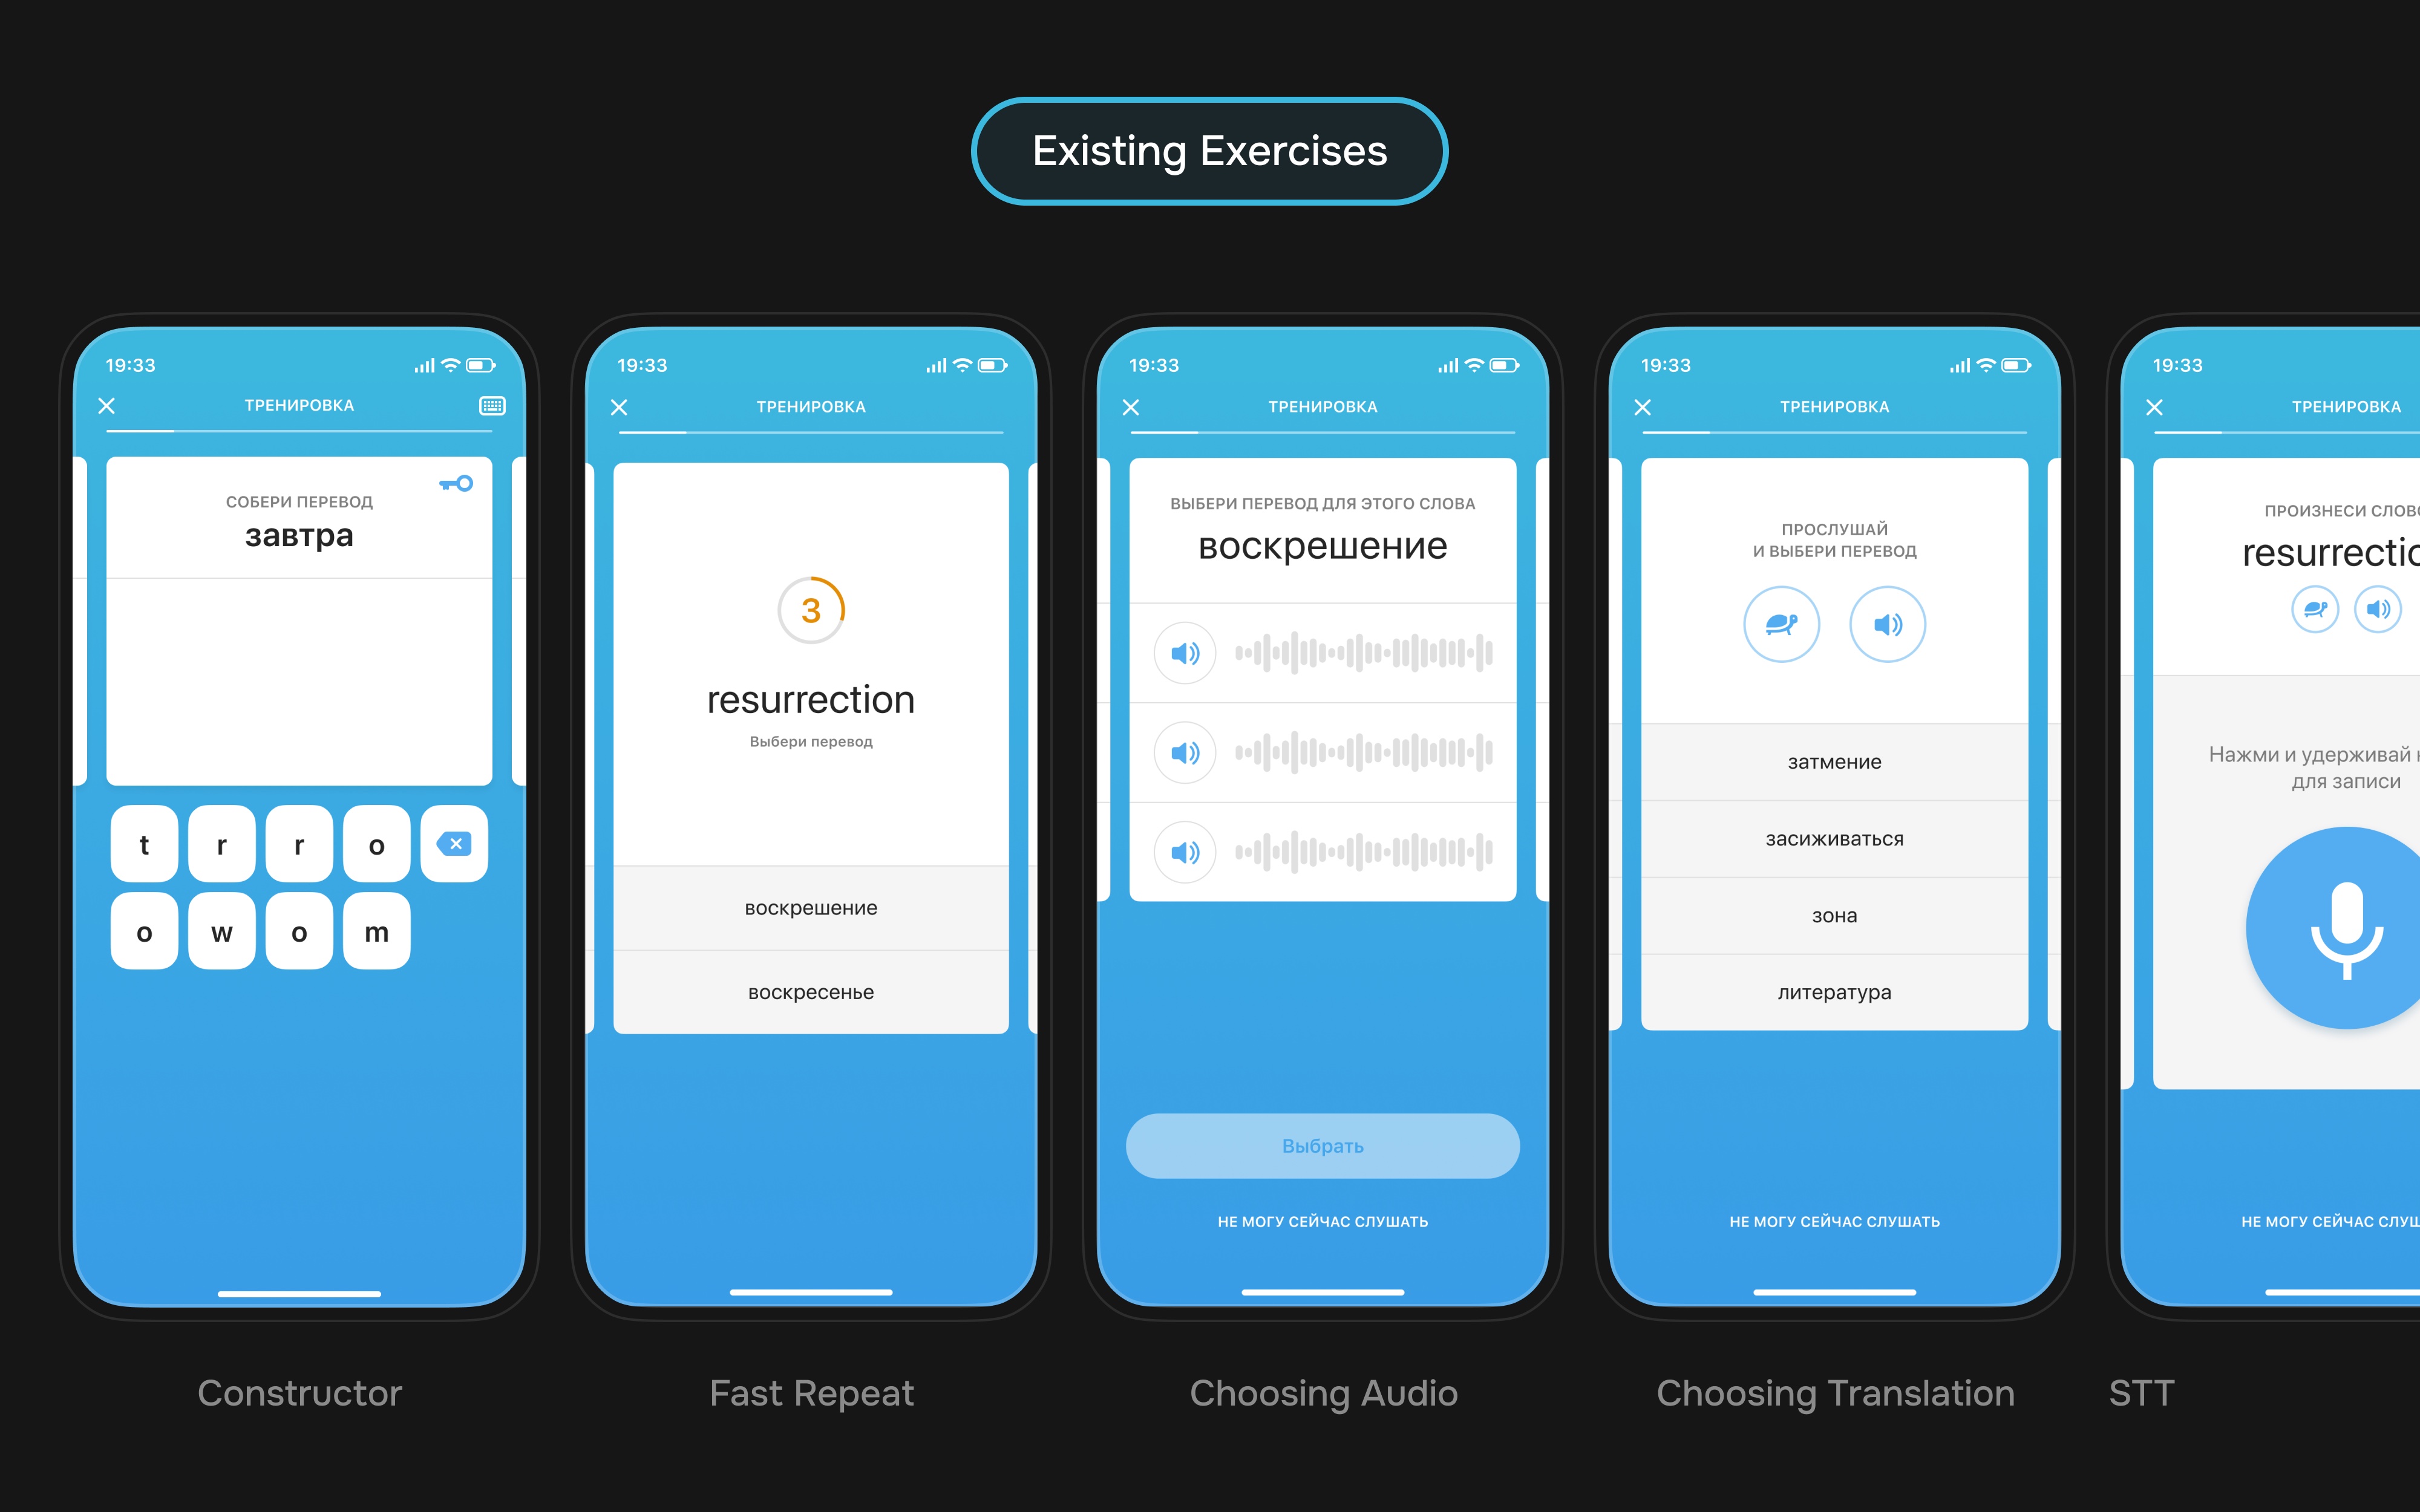
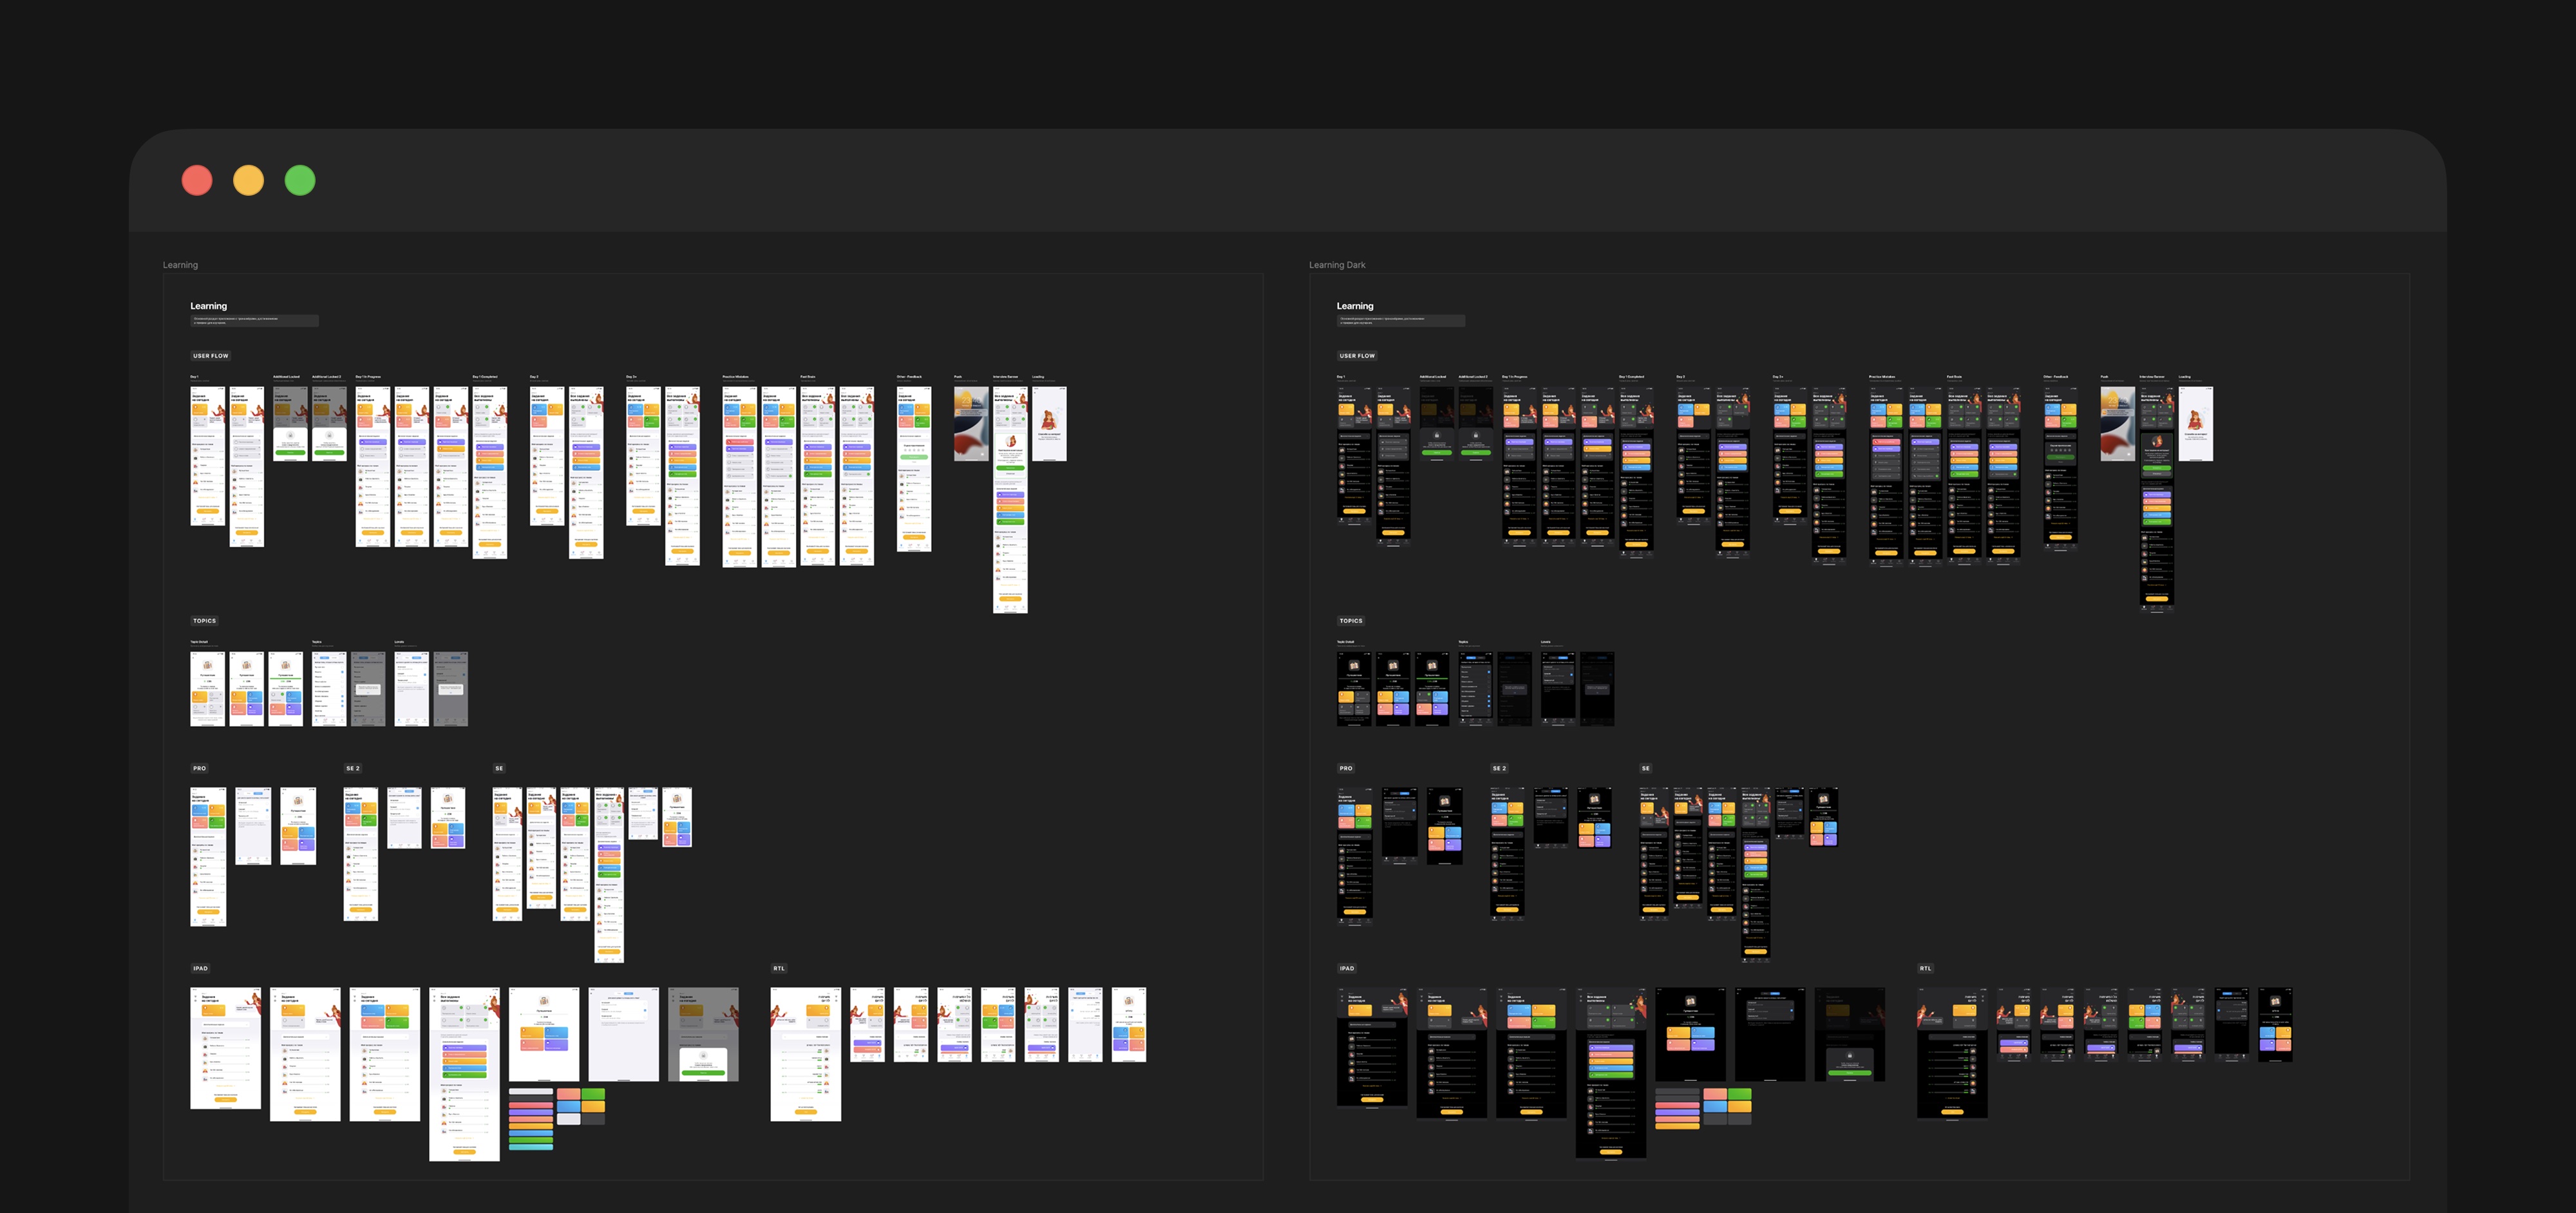
The feature had to preserve the recognizable Bright mechanics: cards, progress, correct and incorrect answer popups, audio, hints, and the feeling of a short exercise. I used the existing trainers as the base, but slightly refreshed the style within this project: softer cards, more rounded corners, and the same visual updates for older exercises.
Training Logic
The most interesting part was material selection. The client kept a JSON history of views: the word, the sentences for that word, and the exercises for each sentence. The next iteration selected items with the lowest counters, so users saw new and older words in the right proportion while sentences gradually became more difficult.
| Level | What Was Stored | Why |
|---|---|---|
| Word | How many times the word appeared in the training | Mix new and older words without overloading users with the same items |
| Sentence | Views and initial difficulty from the database | Show simpler sentences earlier and harder ones after repetitions |
| Exercise | A counter for each exercise within a specific sentence | Balance exercise types and gradually introduce harder mechanics |
New Exercises
The feature introduced several exercises of different difficulty: insert one word, insert several words, type a word, build a sentence from blocks, build a sentence from audio, and pronounce a sentence. This let the same word be practiced through different channels: reading, meaning, word order, listening, and pronunciation.
Flow Scale
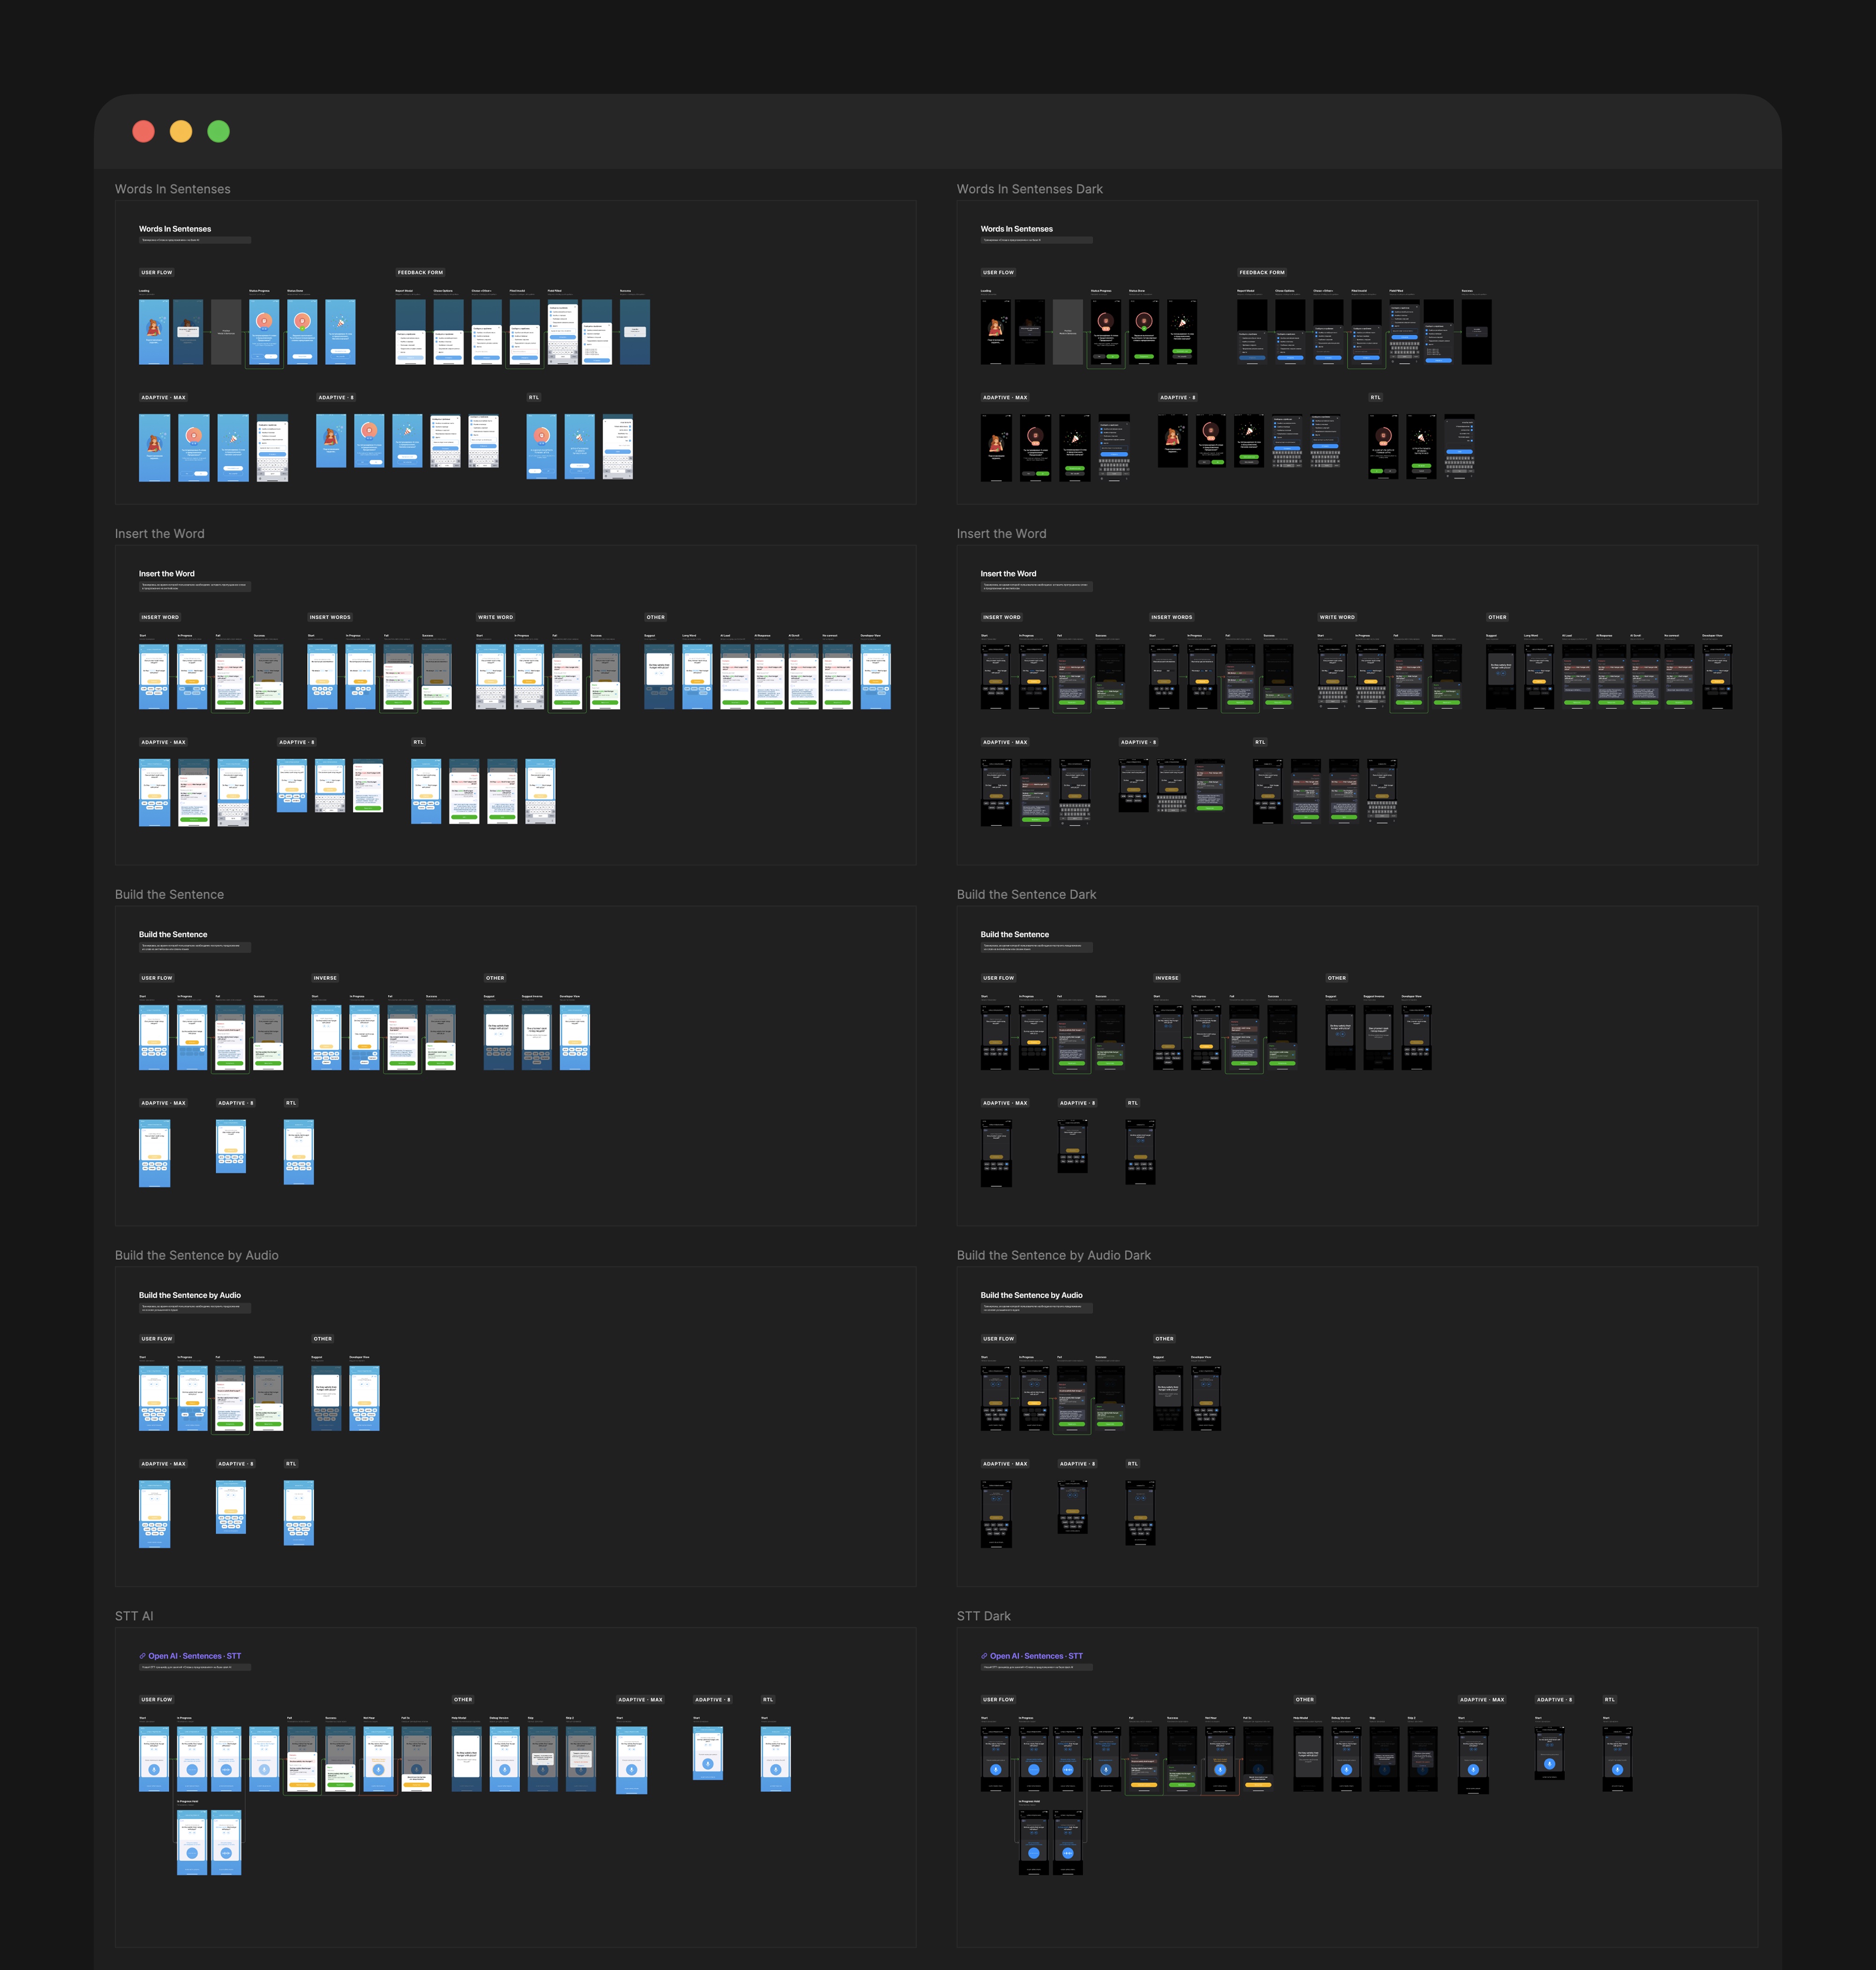
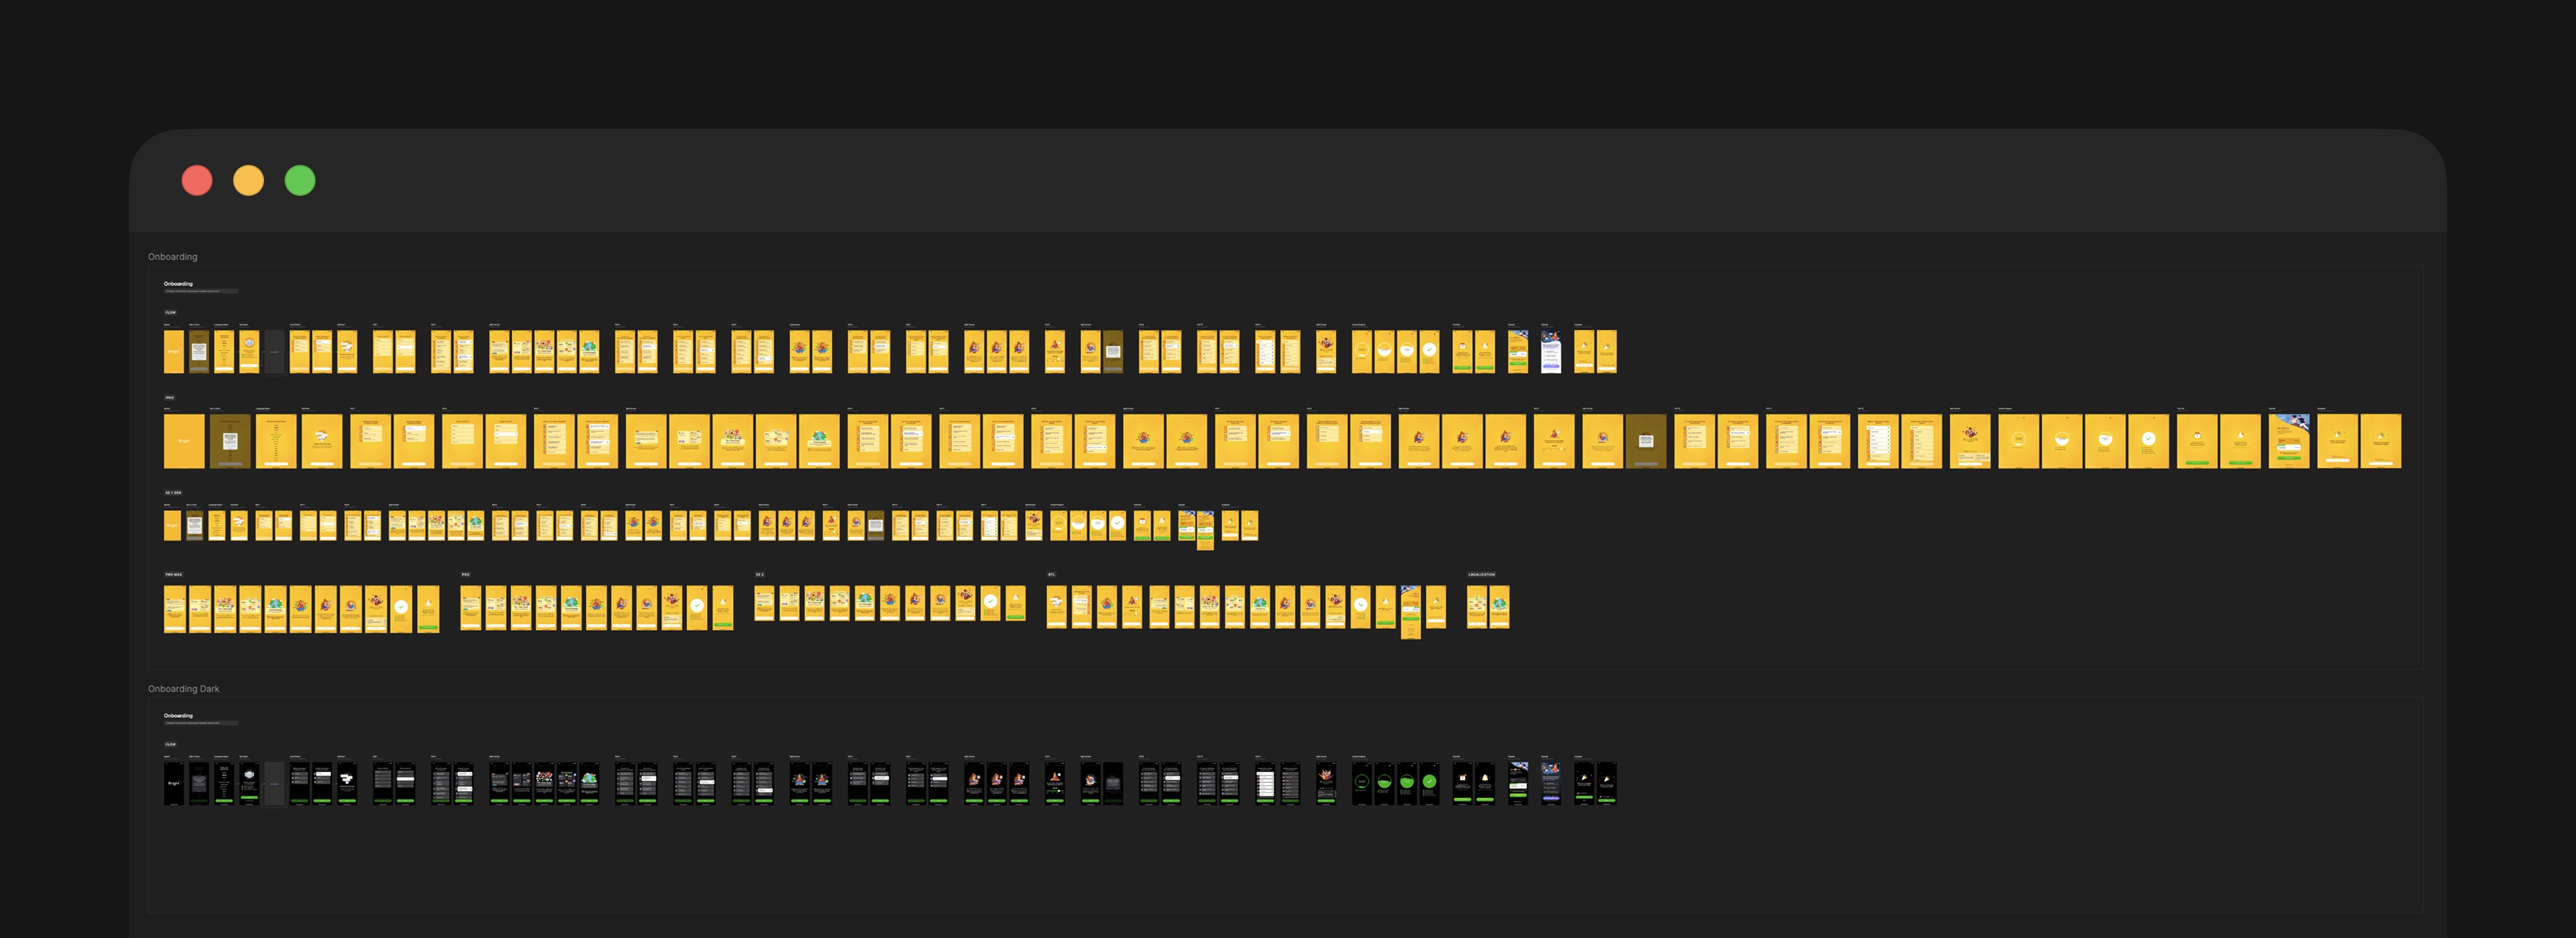
The large storyboard covered much more than the happy path. It had to account for light and dark themes, adaptive screen sizes, RTL, loading states, correct and incorrect answers, sentence feedback, no network, OpenAI response errors, and different ways to finish the training. The image below shows only the iOS part of this work.
Iterations
| Iteration | What Changed | What We Learned |
|---|---|---|
| Initial build | A new home‑screen card, word and sentence selection logic, first exercises, RTL support, and dark theme support. | The feature was large not because of the screens, but because of states, locales, and content‑selection rules. |
| A/B v1, Oct 03‑Nov 10, 2023 | Launched in versions 2.4.34‑2.4.36 for selected locales. Group B received the new training type; group A did not. | Active users showed subscription and ARPU growth, but the training was too long and hurt daily completion. |
| A/B v2.1, Dec 27, 2023‑Jan 31, 2024 | Shortened the training, added an easier native‑language constructor, removed the hardest constructor from early repetitions, and added German and Turkish locales. | The feature became stronger financially and noticeably better balanced, although the daily workload was still high. |
Results
The first version produced an important but mixed result. Across all users, trial‑to‑subscription conversion barely changed, but among active users it grew from 27.8% to 29.2%. Revenue for this segment increased by 6.9%, and ARPU by 5.5%. The cost was high: first‑day completion almost halved, and average daily task time grew from around 14:29 to 29:58.
The second iteration was more mature. Trial‑to‑subscription conversion increased across all users, and among active users the lift became stronger and statistically more convincing. Users completed the new training more often, closed it manually less often, returned to learning more consistently, and made fewer errors inside the training itself.
The key insight was that contextual practice is valuable, but needs careful dosage. A learning feature can be valuable and still too heavy for day one.
Outcome
In the end, Words in Sentences became a new learning layer: users returned to already learned words, saw them in context, and practiced meaning, listening, word order, and pronunciation.
Feature 3. New Home Screen
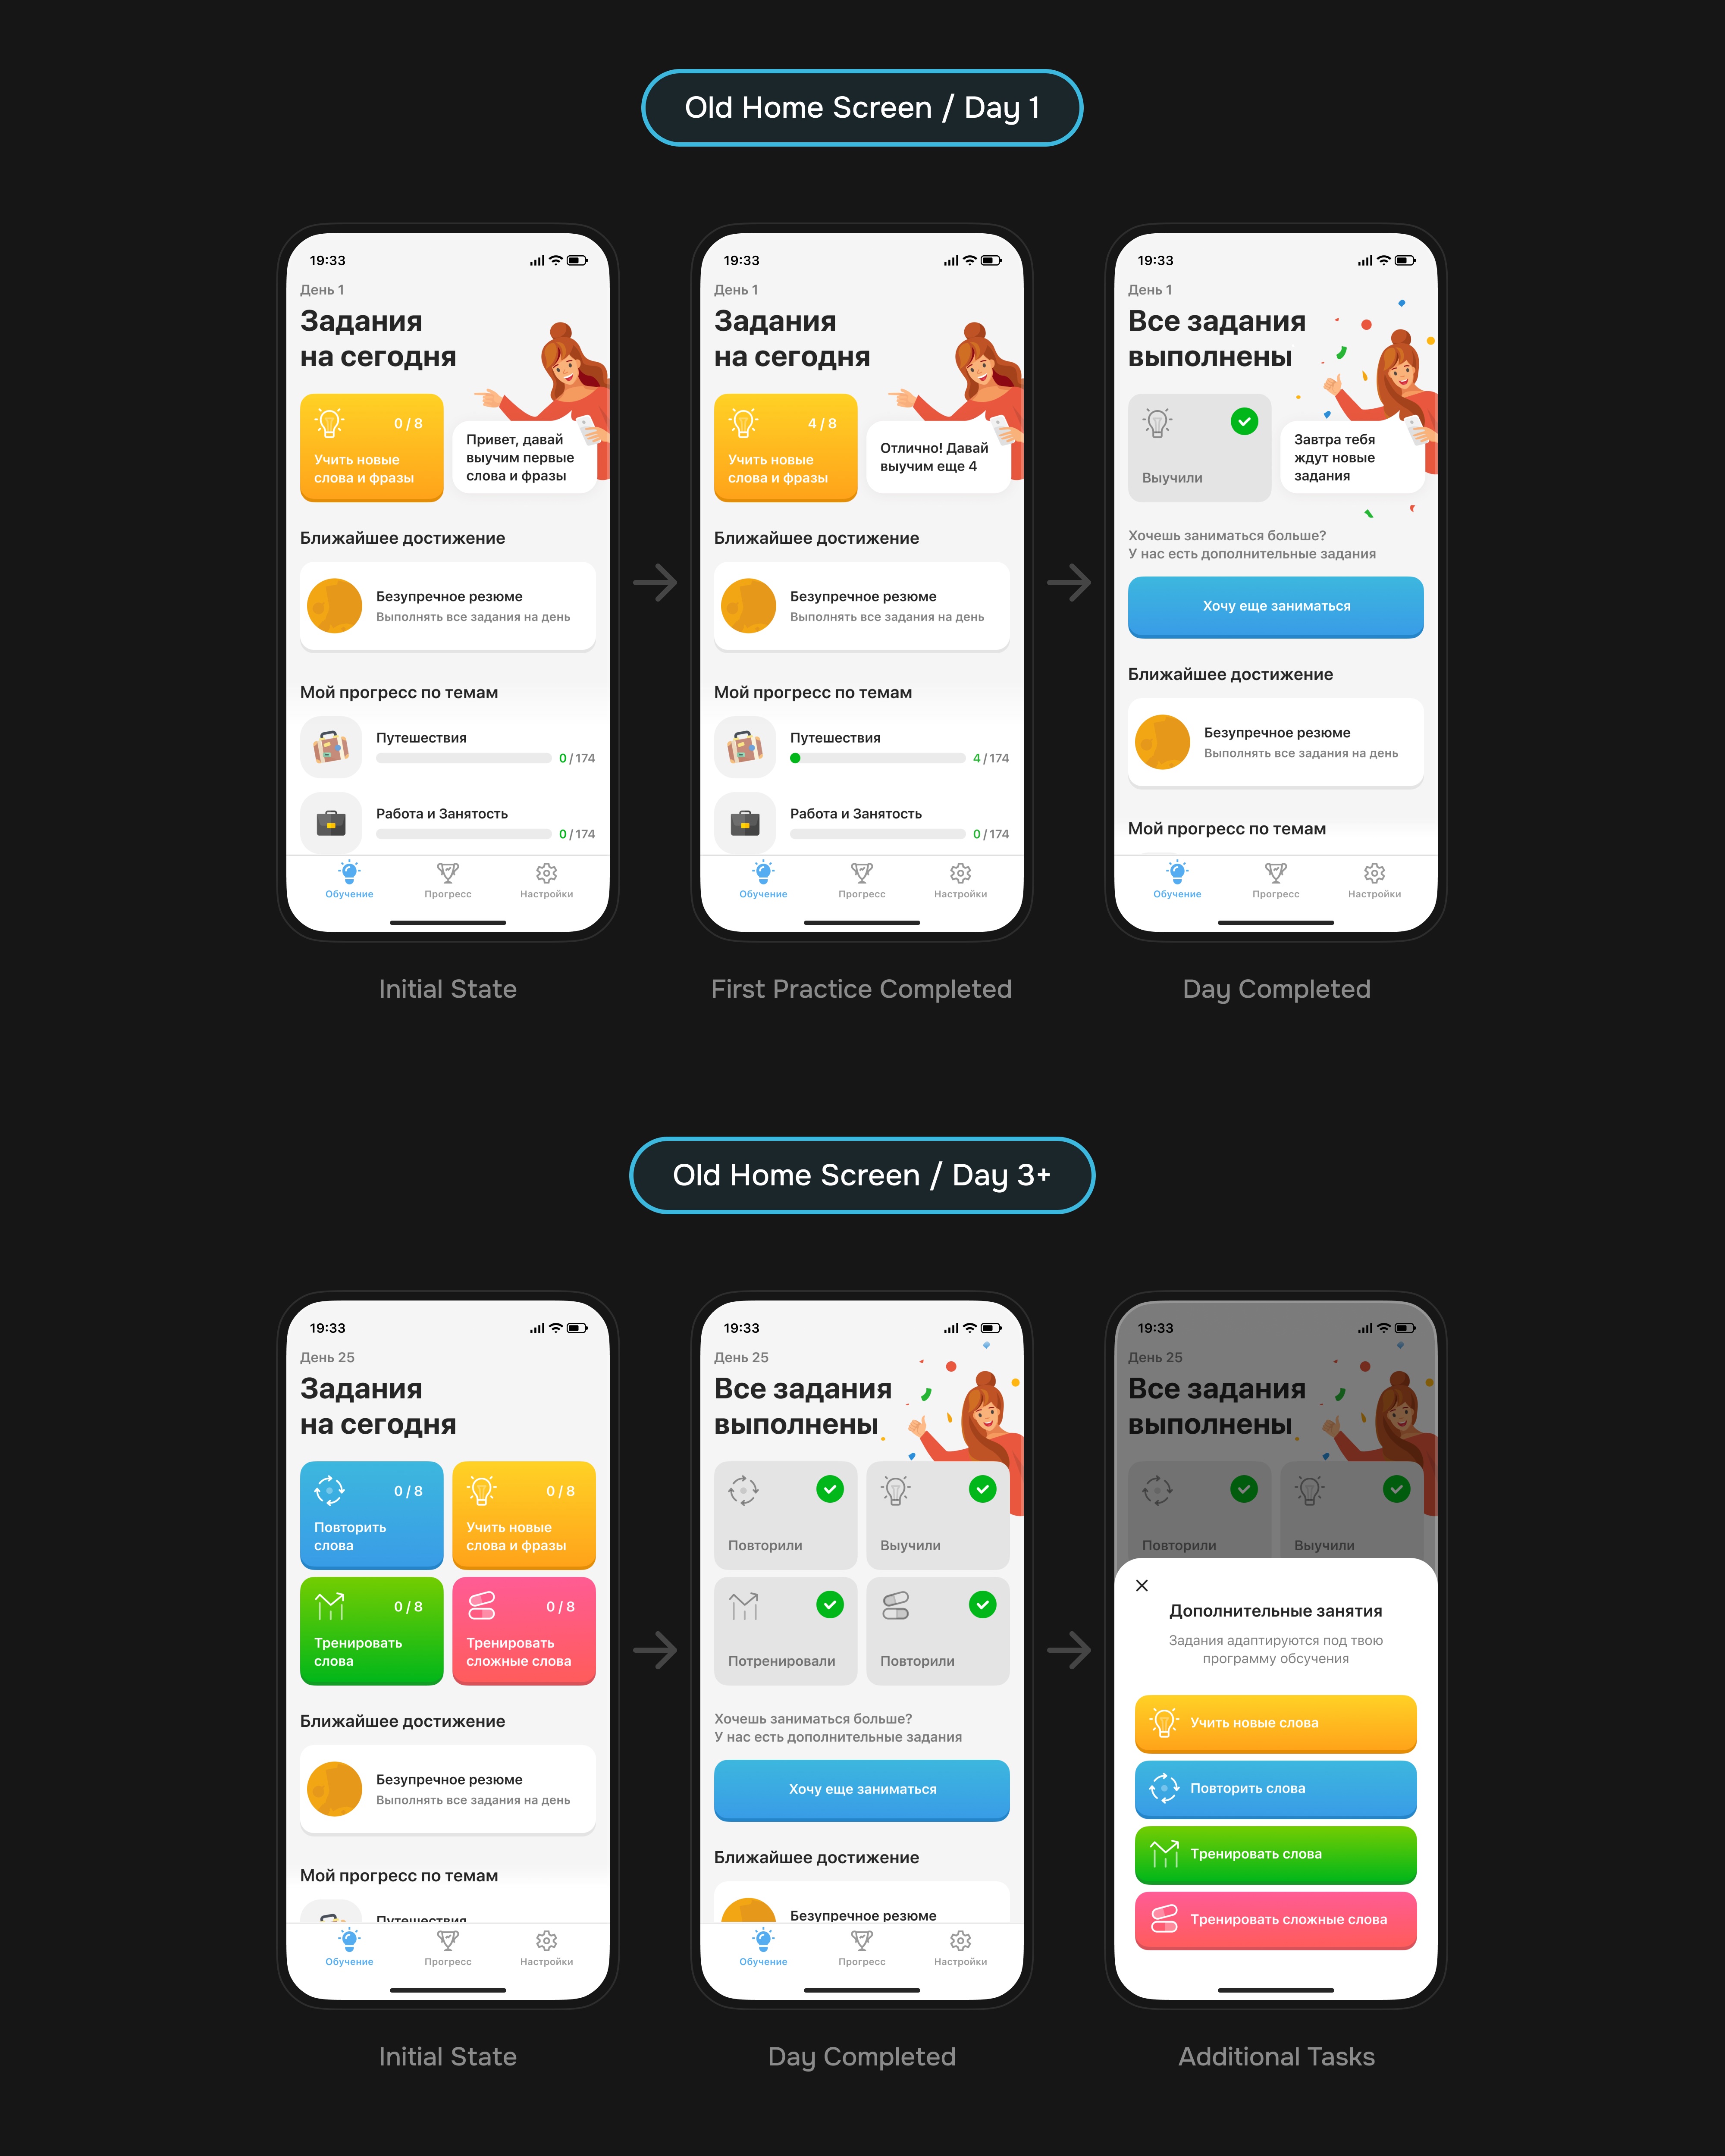
The home screen was the daily entry point into learning, but its logic no longer scaled well. Main exercises were tied together, while extra practice was hidden behind a “Want to keep learning” button that became available only after all exercises were completed.
Hypothesis: if daily tasks become clearer and extra exercises are available immediately, active users will practice more without feeling that the daily workload became heavier.
We tested the new version in an iOS A/B test in version 2.5.1 from February 5 to February 29, 2024. The control group kept the old home screen with an extra‑practice button and Mistake Practice as a main daily task. The test group received the redesigned home screen with an extra‑tasks block available by default, while Mistake Practice became an optional exercise inside that block.
What Changed
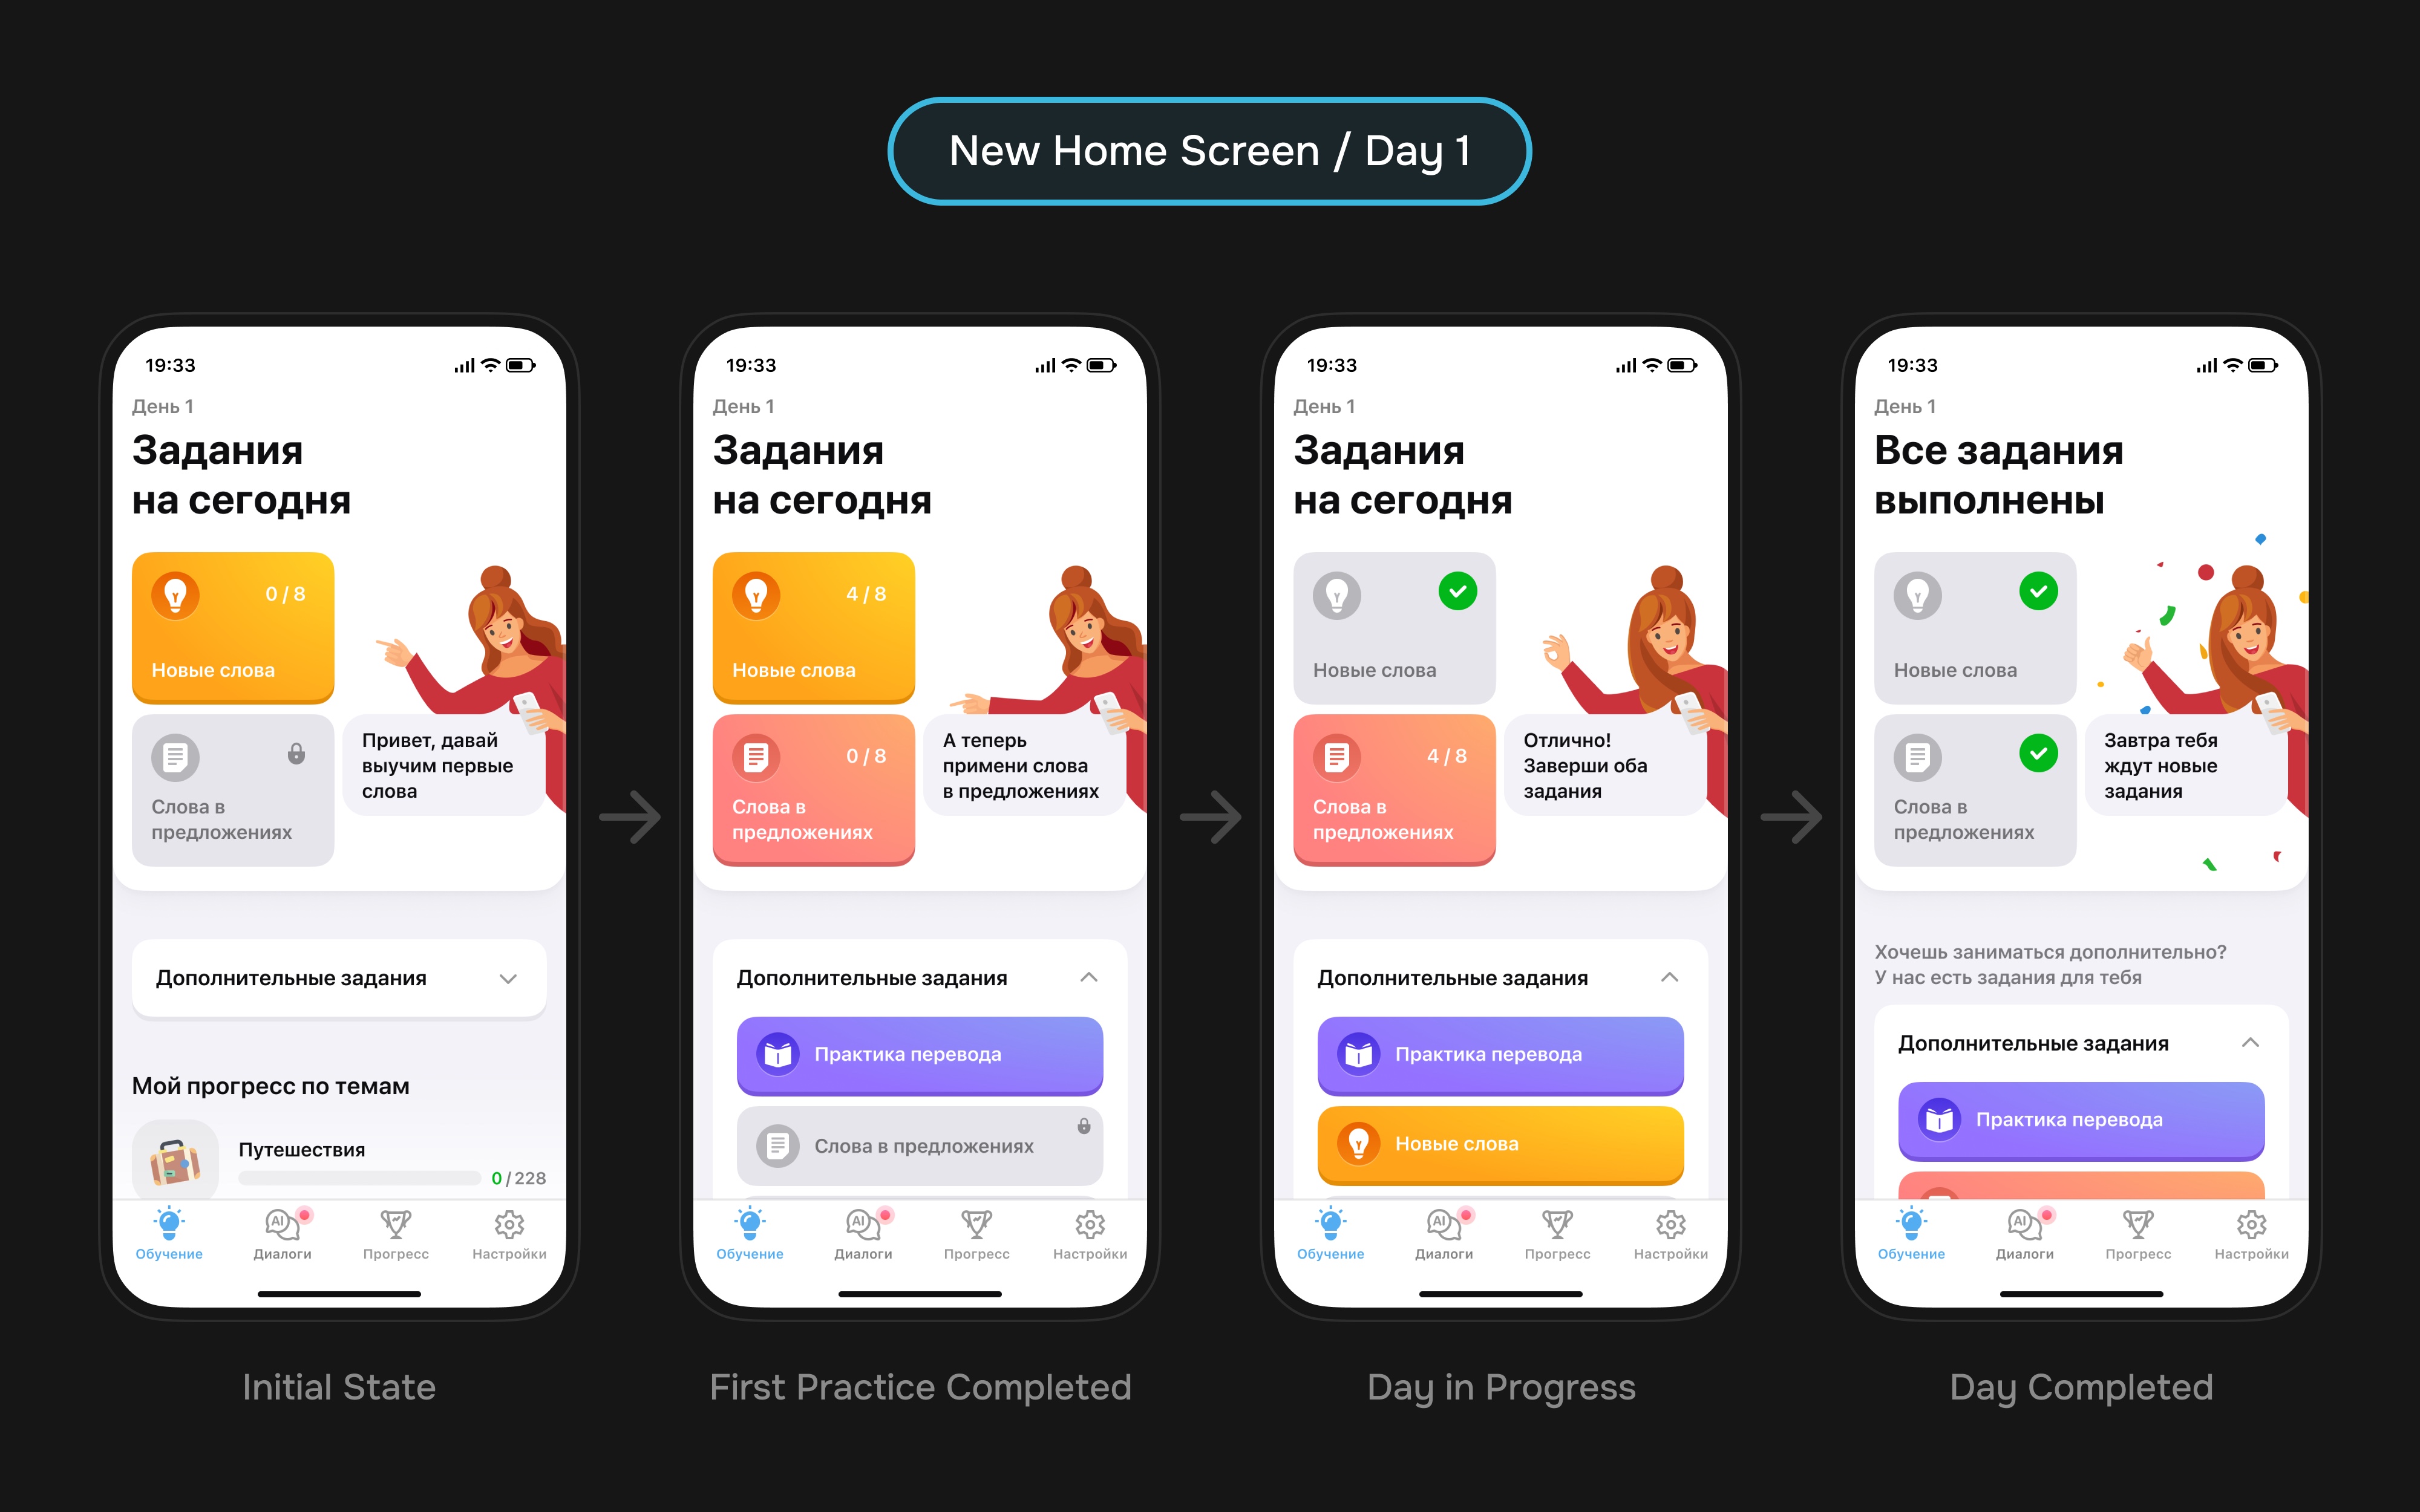
The first step was not just a visual refresh, but a rebuilt screen model. Main task cards became independent: they could be reordered, hidden, locked, highlighted with a pulse state, and reported to analytics with their position. This mattered for future experiments: the home screen had to support new exercises, different learning days, RTL, dark theme, and different devices.
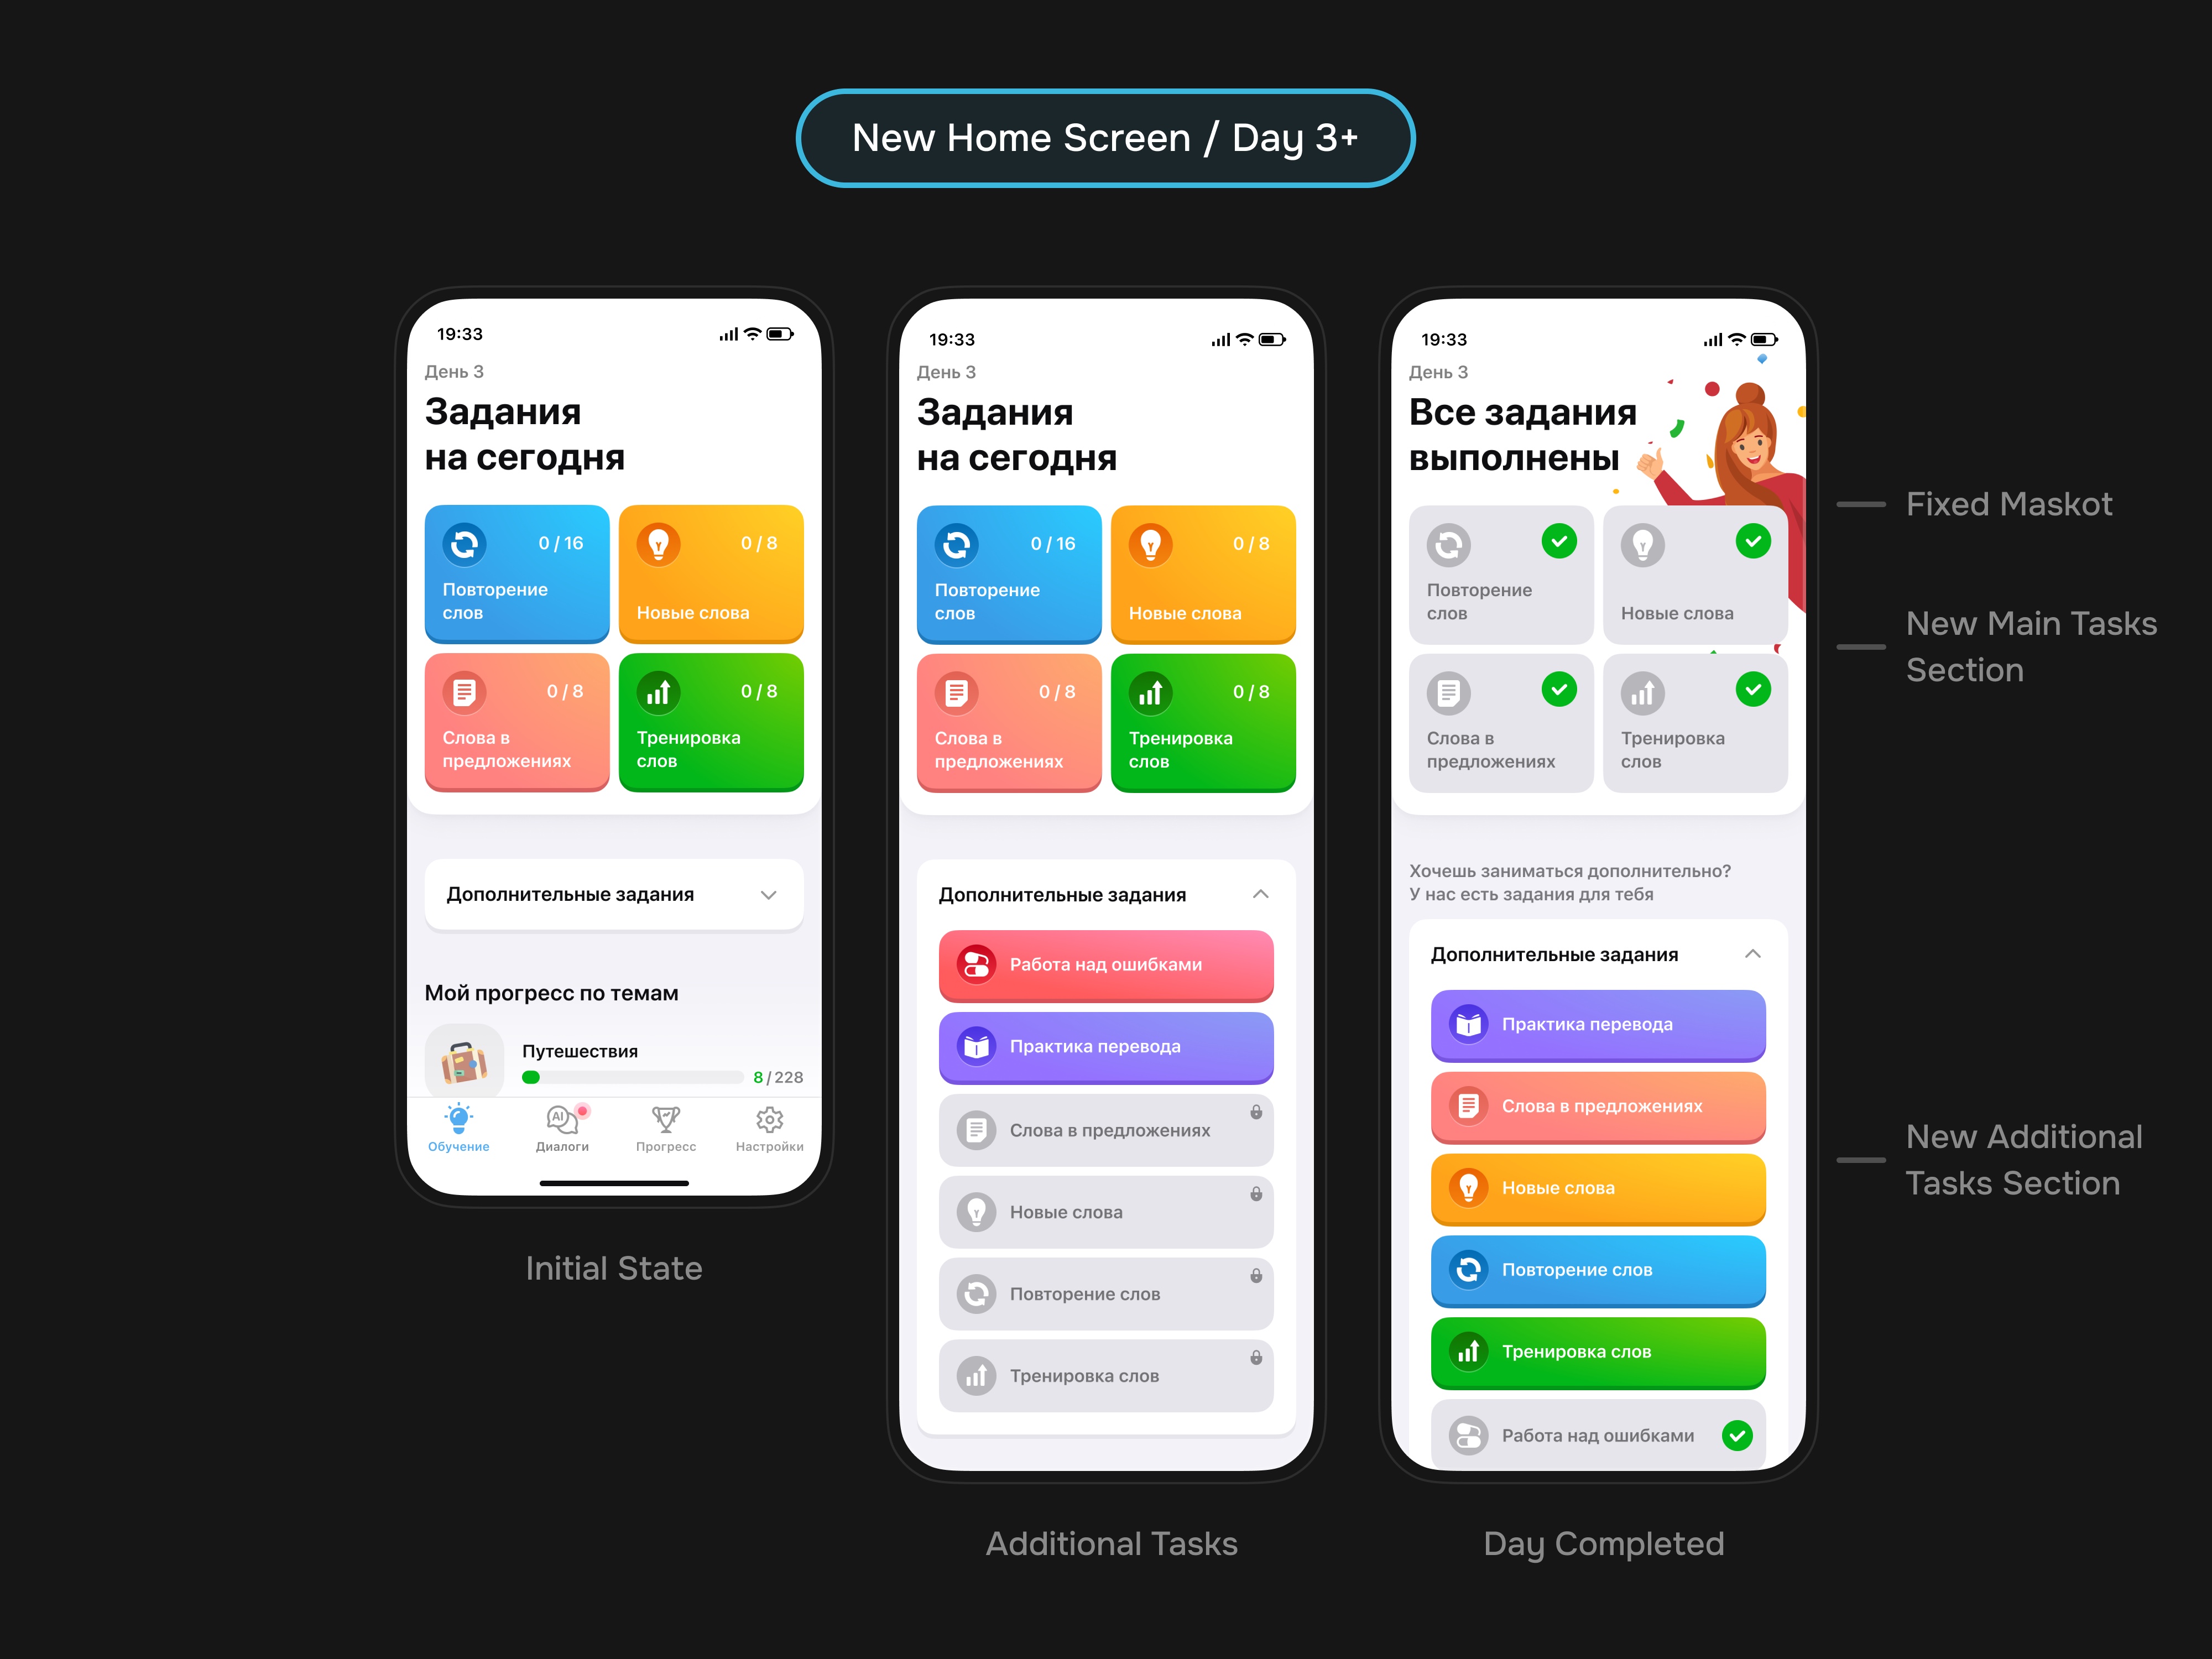
Visually, the screen became clearer: main tasks turned into colored cards with large icons, the background was split into a white learning area and a gray gradient below, and the extra‑tasks block became a visible part of the home screen. After all daily tasks were completed, it expanded automatically and offered continued practice as an understandable next step rather than a hidden bonus.
Extra‑Task Logic
The main product work was availability logic. The extra‑tasks block was always present on the screen, but collapsed at the start of the day. Users could expand or collapse it manually, and this state was preserved within the session. After daily completion, the block expanded automatically, and the top available card pulsed until the user completed one extra exercise iteration.
The Words in Sentences card had to live on the home screen every day and be available in the extra‑practice block. But on day one, the user might not have enough learned words for this training, so the card needed a disabled state. Depending on the number of learned words, one iteration used 4 or 6 unique words.
| Task | When It Appears | Key Rule |
|---|---|---|
| Mistake Practice | From day 3, if enough difficult words exist at the start of the day | No longer required for daily completion; after completion it moves down as completed |
| Translation Practice | If enabled by config | Locked until the user has learned at least 6 words |
| Words in Sentences | If the training is available in the locale | Locked until the matching main daily task is completed |
| New Words and Repetition | On days one and two, available as extra cards only after the main rules apply | Repetition requires at least 8 learned words; both tasks are locked while the matching main card is unfinished |
| Word Training | From day 3 | Shown when the queue has 16+ words; after all queued words are trained, it becomes completed |
A/B Test Results
Financial metrics across all users were mixed because of an imbalance in the passive audience: overall trial‑to‑subscription conversion barely changed, 28.3% versus 28.4%. But among active users, the trend was positive: trial‑to‑subscription conversion grew from 30.8% to 31.8%, and in locales with AI exercises, from 27.6% to 29.2%. First‑year LTV revenue grew by 2.2%, and by 6.2% among active users.
The behavioral effect was much clearer. Users started their first exercise from the home screen more often: the split between starting from the card and from a topic moved from roughly 60/40 to around 80/20. Extra‑task starts more than doubled, and the average number of exercises grew across all types, especially Repetition and Words in Sentences.
The main takeaway: the redesigned home screen did not just refresh the interface. It changed how motivation was distributed. Mandatory work became lighter, optional work became more visible, and active users got more reasons to keep practicing.
Outcome
As a result, the home screen became a more flexible product surface. It could manage daily workload more carefully, promote new exercises, expose extra tasks without hidden buttons, and support future experiments with cards and their order more easily.
Feature 4. New Onboarding
Onboarding was one of Bright's most sensitive product surfaces: it was where users chose their language, level, topics, saw the paywall, and made the first trial decision. A large redesign could not be shipped in one leap, so we split the work into three iterations and tested each separately.
Hypothesis: if onboarding becomes a personalization survey instead of a set of separate intro screens, users will understand Bright's value before the paywall and will be more likely to start a trial.
Core Changes
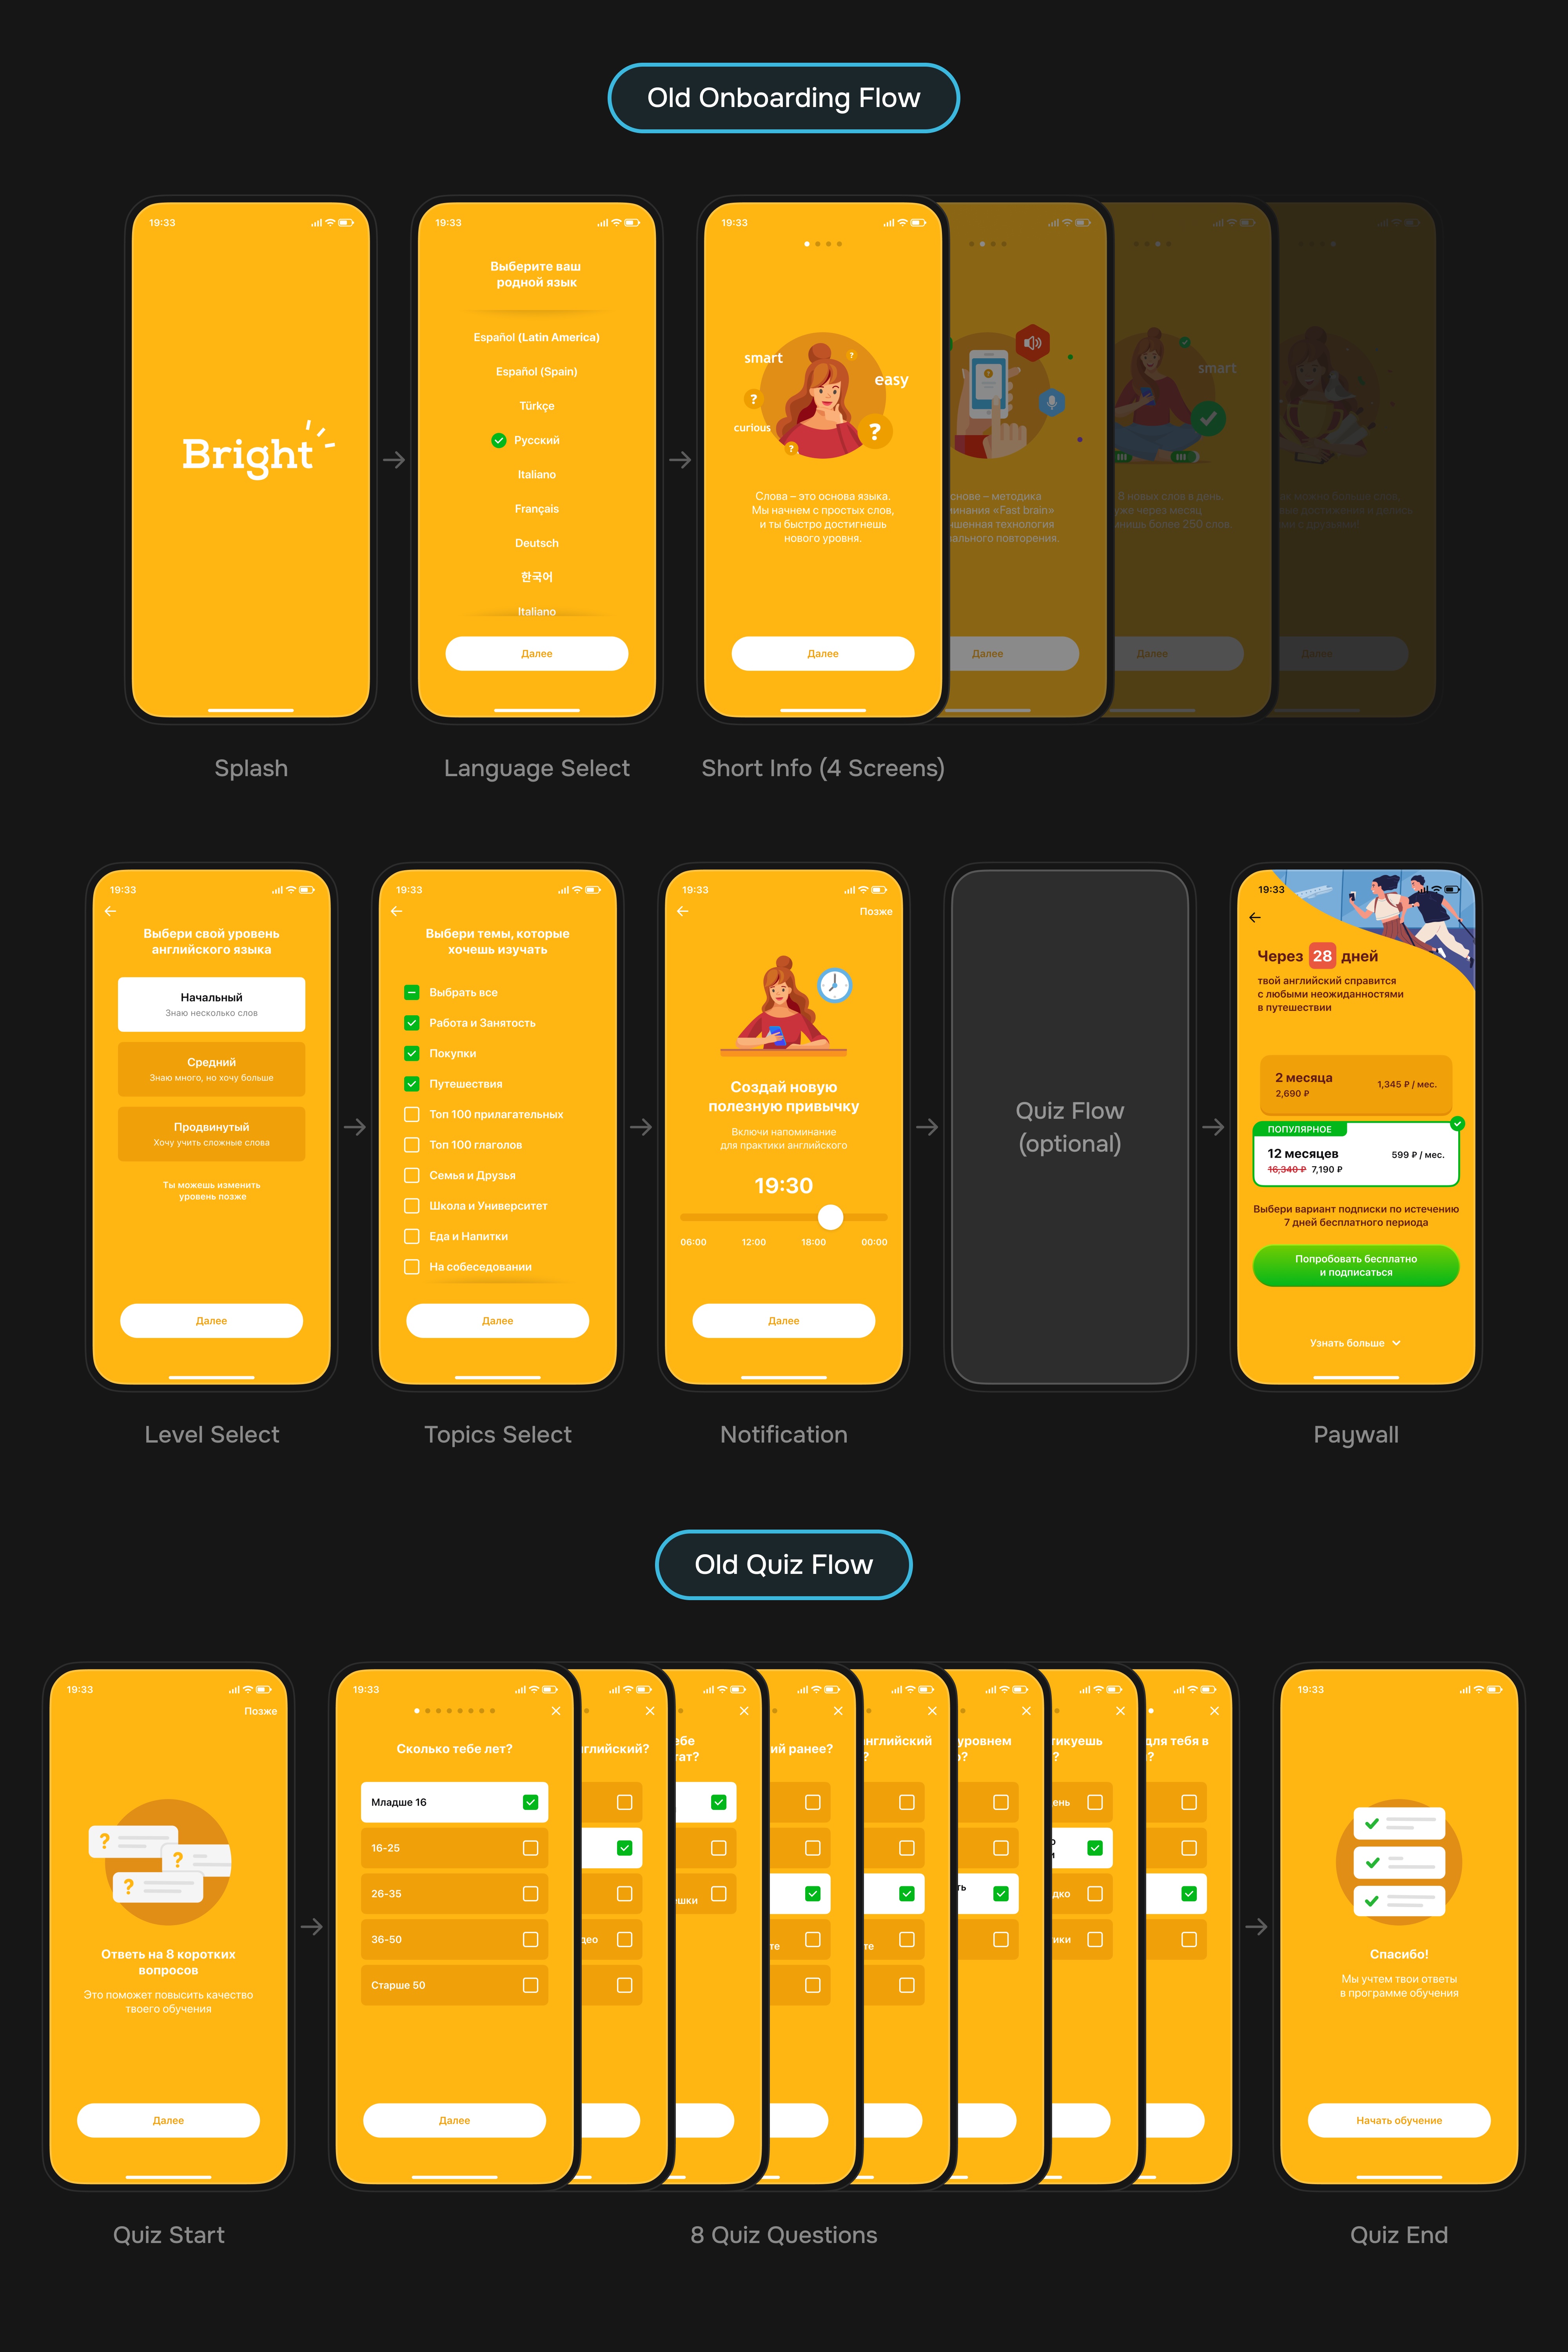
In the first iteration, we started with architecture and screen order. Onboarding had to become modular, so the team could add, remove, and reorder screens without breaking topics, notifications, paywall content, analytics, or returning users to their last step.
| Before | After | Why |
|---|---|---|
| Several separate intro screens before the survey | One required survey with top progress bullets | Center the first experience around personalization, not a generic product presentation |
| The quiz could be skipped | The survey became required and longer, but clearer and more structured | Collect data for level, topics, study pace, and paywall messaging |
| Topics were selected earlier in the old flow | Topics moved toward the end of the survey | First understand motivation and constraints, then offer a program |
| Study pace settings were less directly tied to answers | The daily‑time answer set the default word count: 4, 8, or 12 | Reduce early overload risk and make the promise more realistic |
Iteration 1. Survey Flow
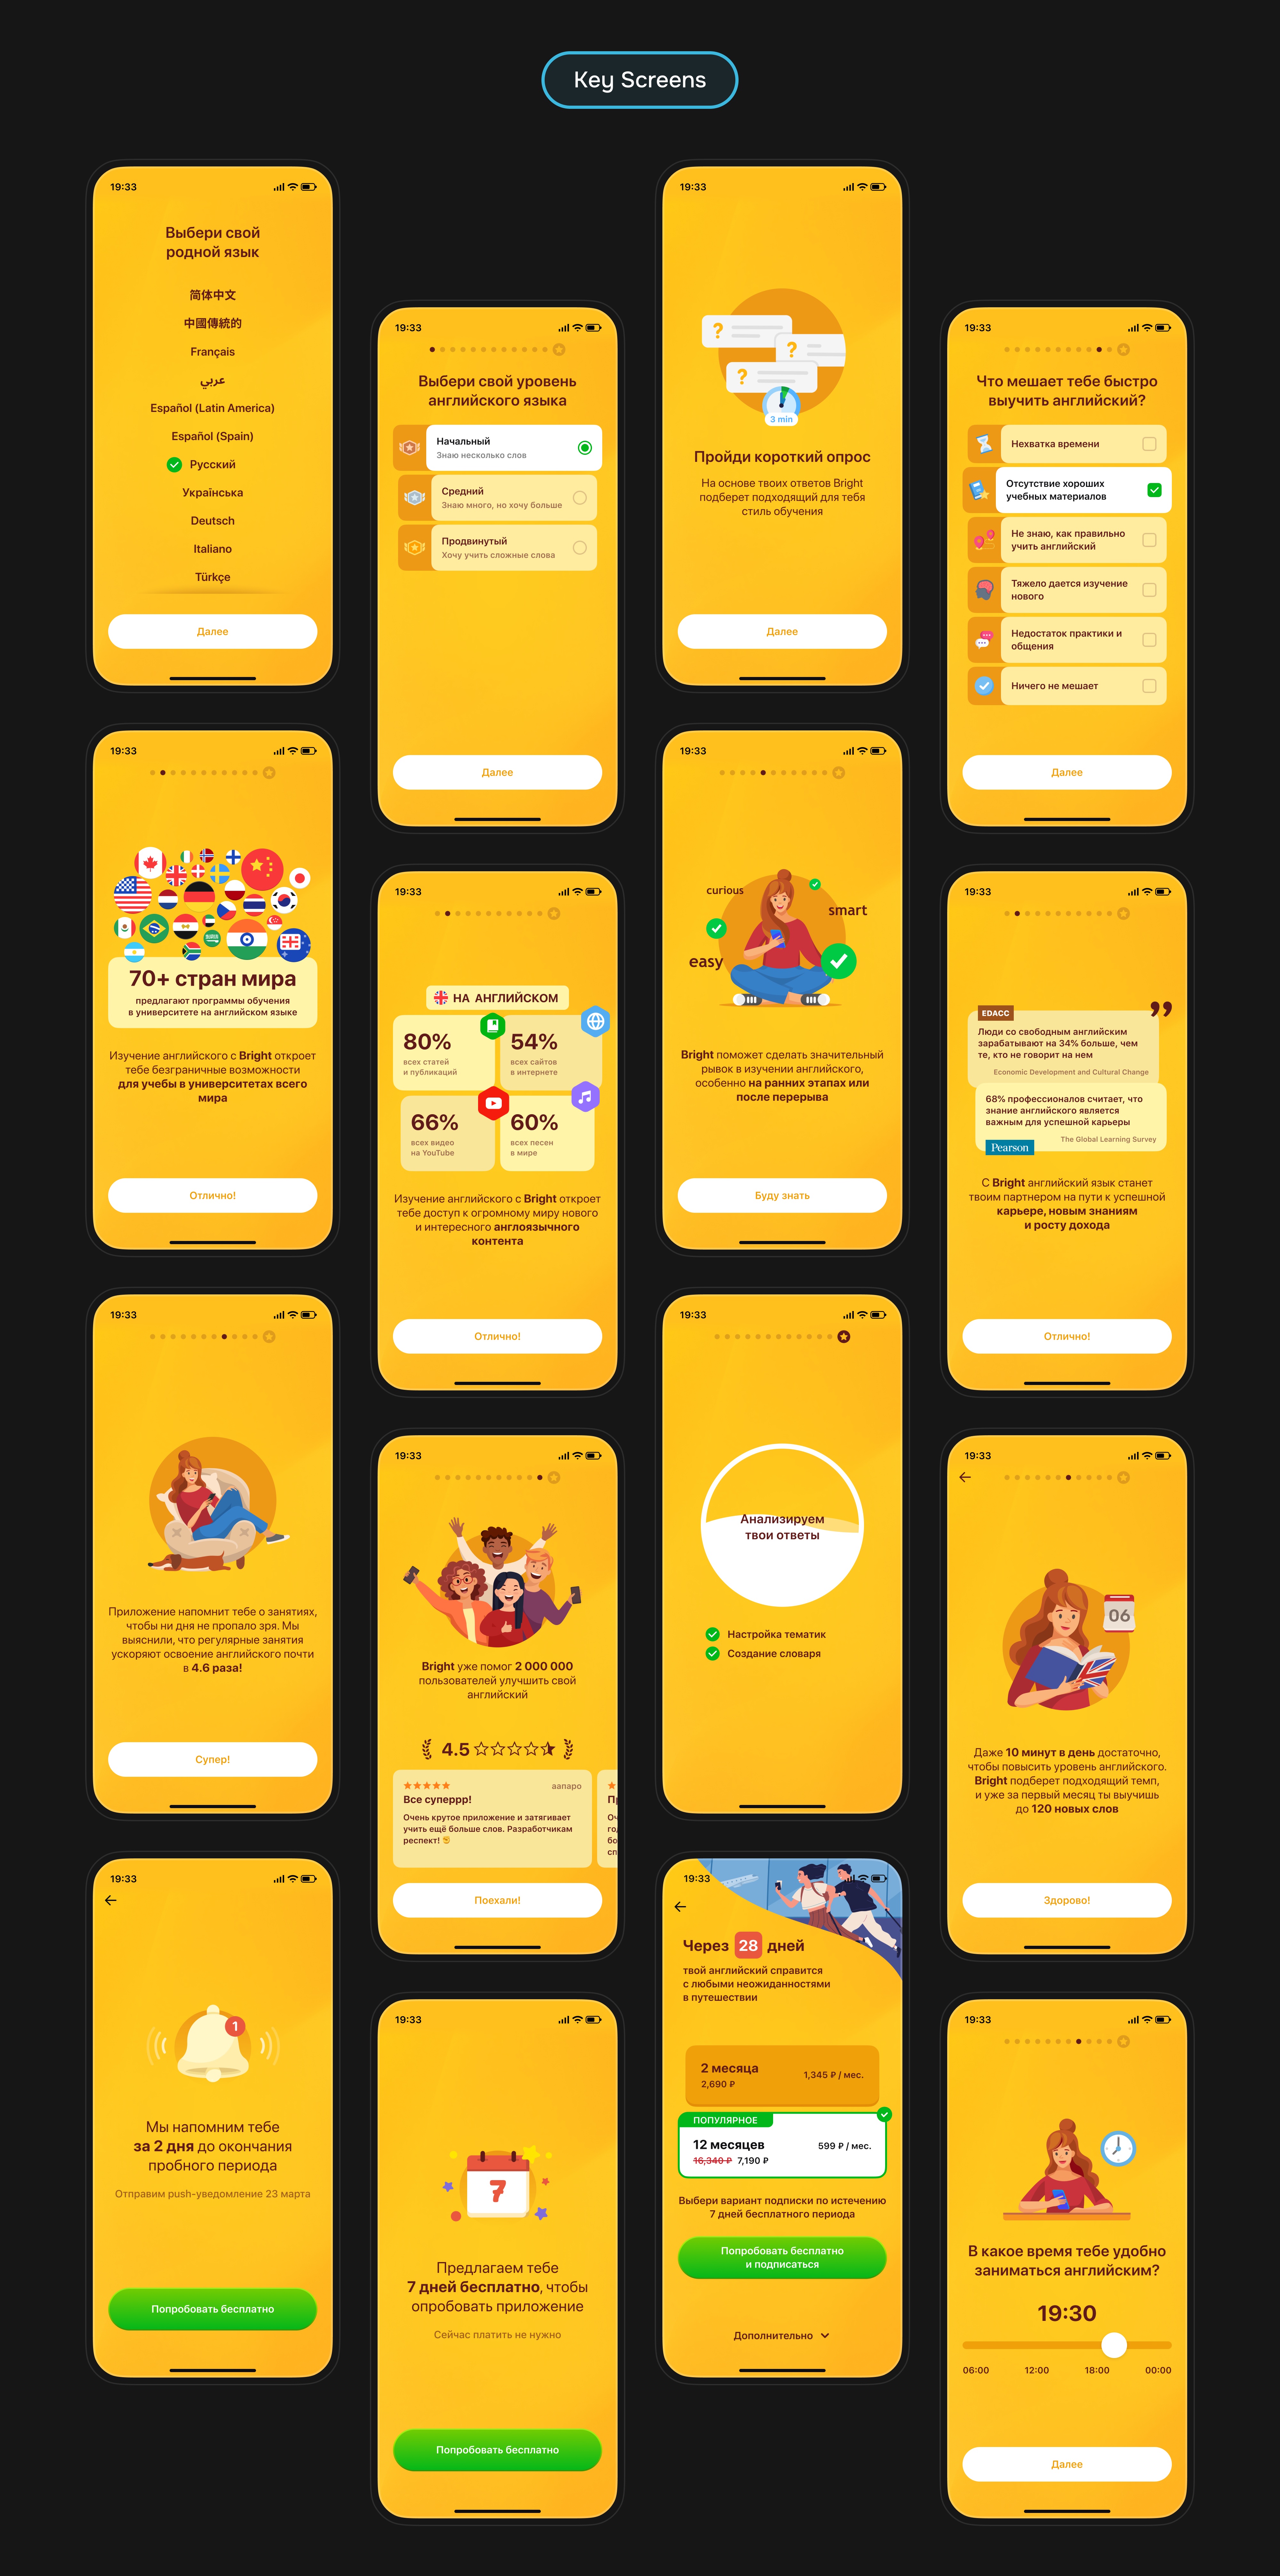
The first iteration shipped in versions 2.6.1‑2.6.2 and was tested from July 11 to August 15, 2024 across 14 locales. Group A saw the old onboarding, while group B saw the new survey flow. The main question was not whether the screen looked better, but whether a required survey would preserve conversion.
The win had nuance. Fewer users reached the paywall: 81.5% versus 77.4%. But those who did reach it converted to trial better: paywall‑to‑trial grew from 15.3% to 16.6%. That was an important product signal: the new onboarding filtered some users earlier, but increased intent among those who completed it.
The main lesson from iteration one: a required survey can work if it does not just ask questions, but helps users understand how their answers shape the learning program.
Iteration 2. Split Screens
In the second iteration, we added split screens: short motivational screens shown after selected questions. Some depended on the user's answer: learning goal, current study method, and daily time commitment. Two more were shared: one about consistency and one with social proof before the loader.
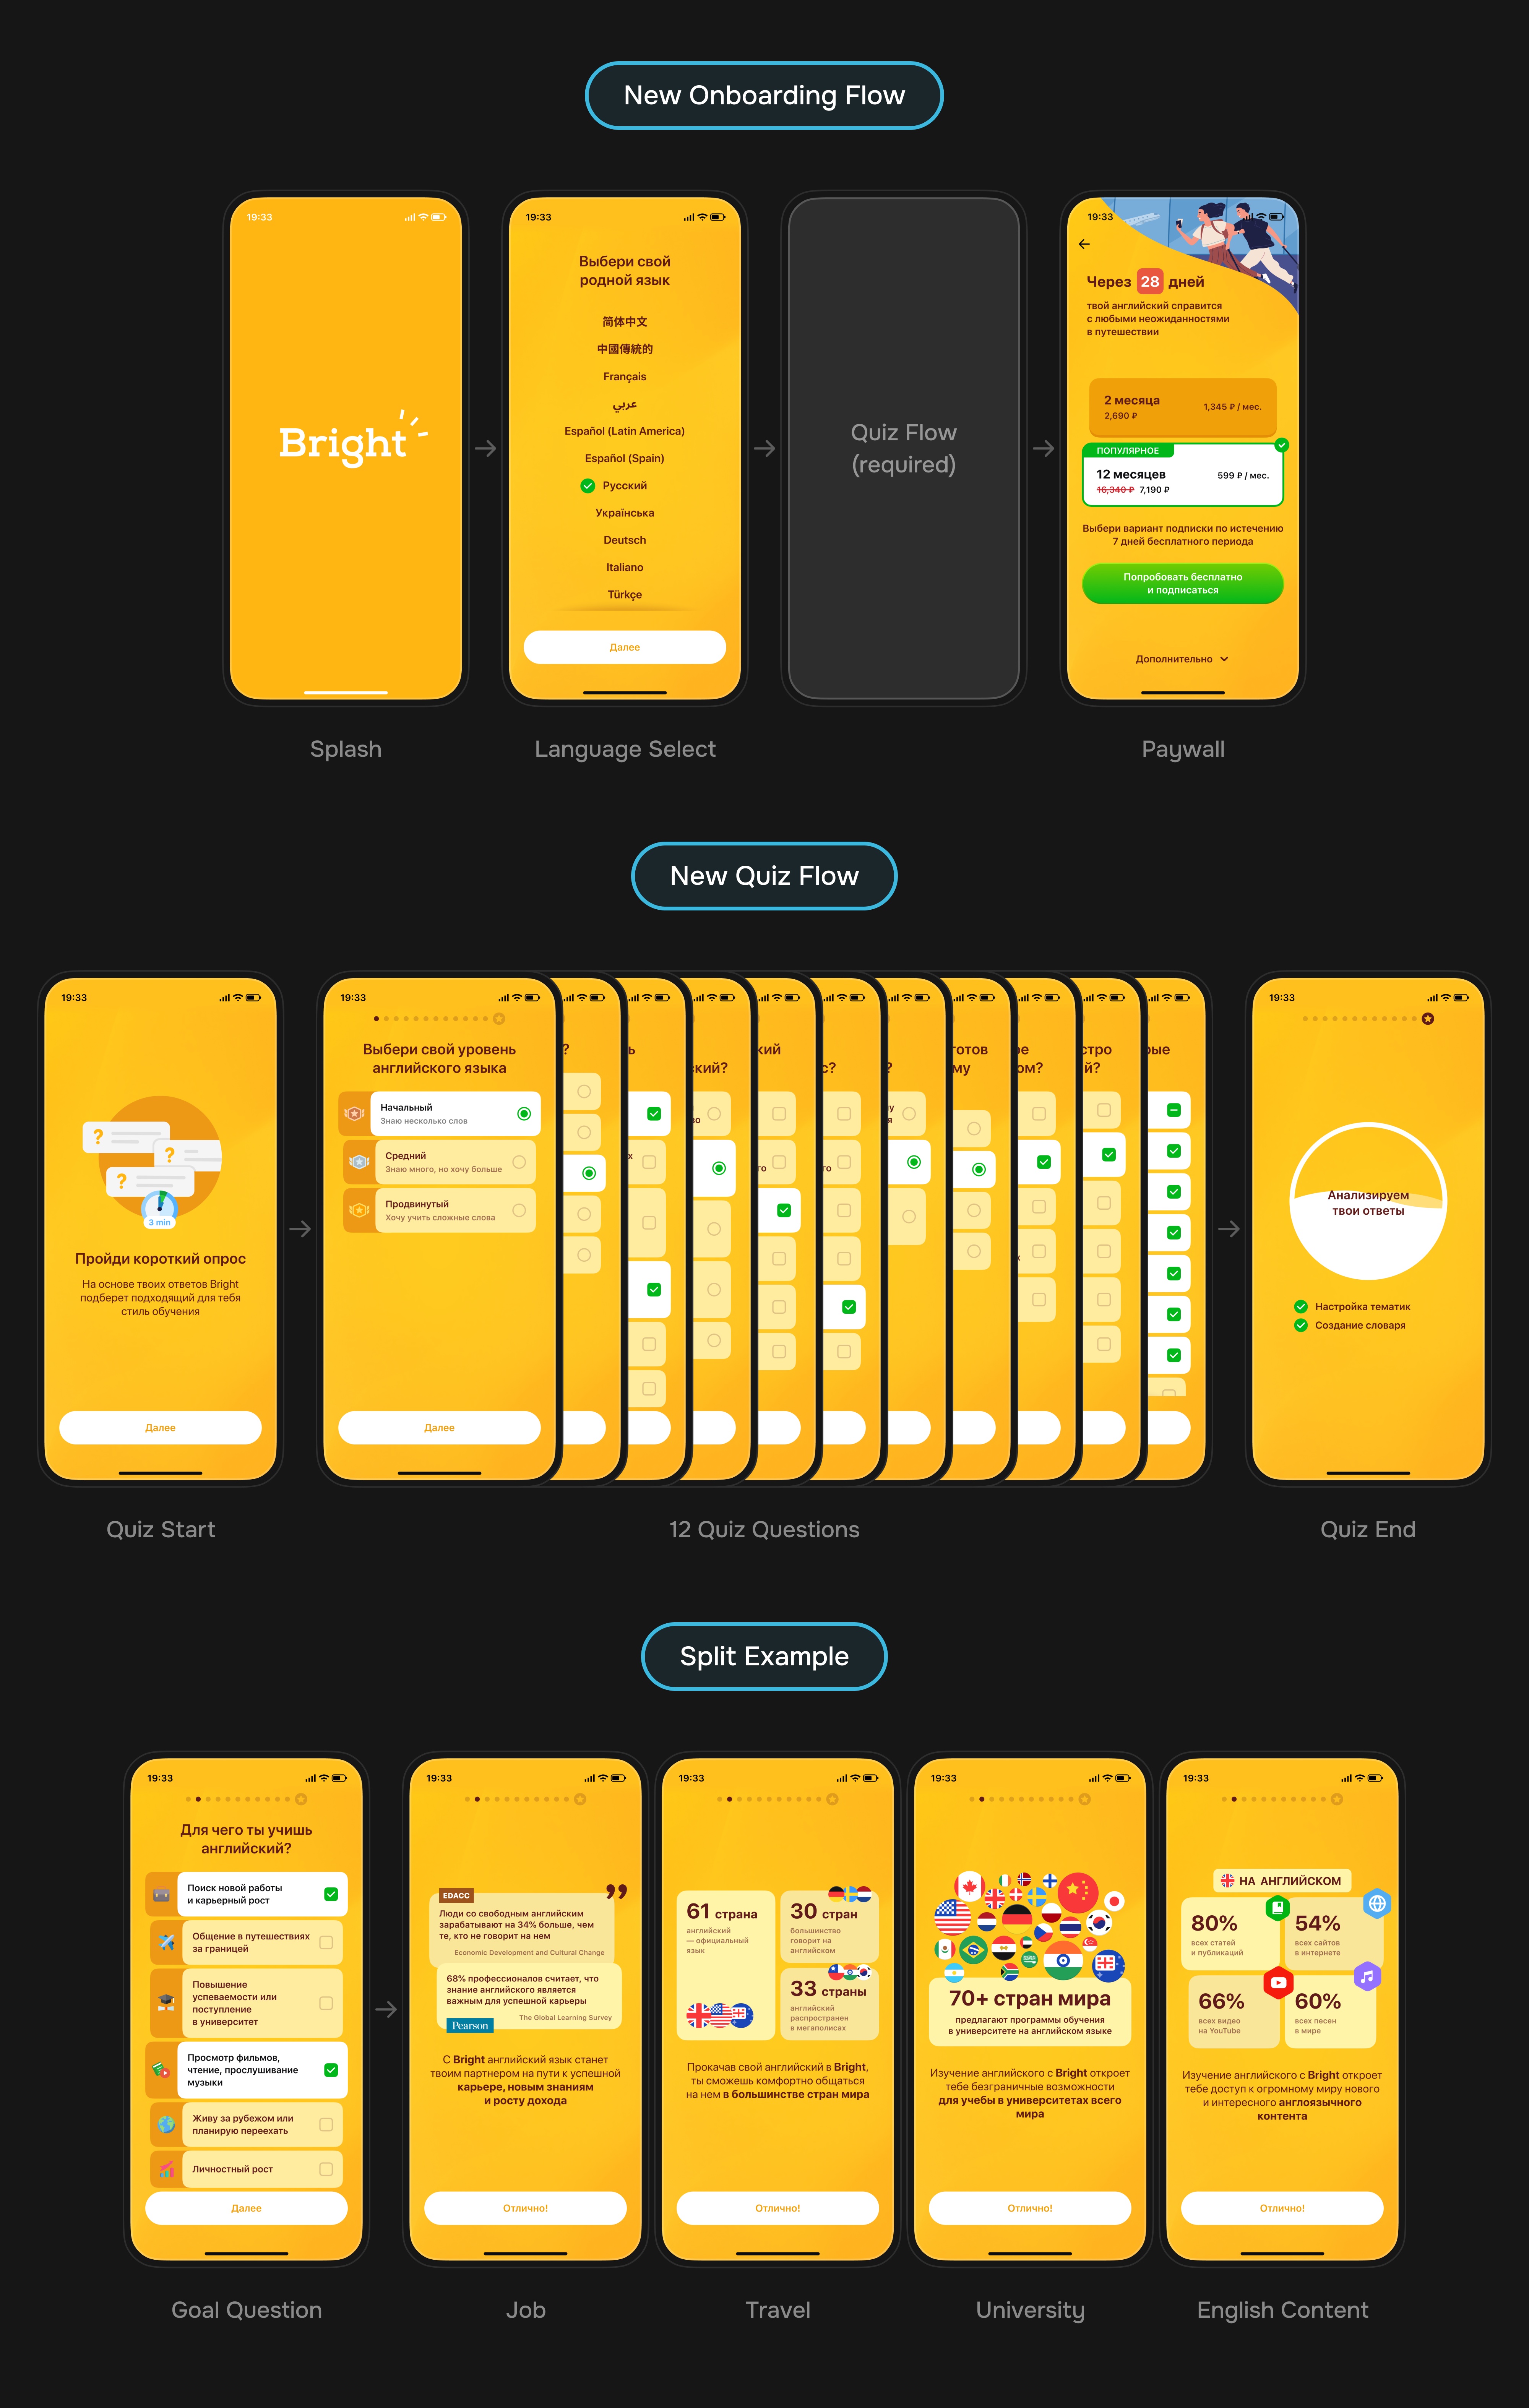
| Split | Trigger | What It Reinforced |
|---|---|---|
| Learning goal | Work, travel, relocation, university, content, personal growth | Users saw an argument tailored to their motivation |
| Current study method | Self‑study, apps, or not studying; versus tutor, school, or native speaker | Bright was framed either as the main method or as support for existing learning |
| Daily time | Up to 10 minutes, 10‑20, 20‑60, or more than an hour | The pace and word‑count promise became realistic |
| Notifications and reviews | Shown to everyone near the end | Supported consistency and trust before trial info |
Financially, the second iteration was stronger than the first: the main lift came at the trial‑info‑to‑subscribe step, 58% versus 62.5%. But there was a cost here too: the new loader after the survey lasted 7 seconds and caused visible drop‑off, 3.7% versus 1% on the old screen. That became a separate recommendation for the next improvement.
Iteration 3. Visual A/B/C
The third iteration was an A/B/C test in versions 2.7.4‑2.7.5 from February 5 to February 25, 2025. At this stage, we no longer changed onboarding logic: we tested three visual treatments — the baseline yellow version A, the solar version B, and the white version C.
| Group | Variant | Outcome |
|---|---|---|
| A | Onboarding v2: standard yellow visual treatment | Control group |
| B | New solar visual treatment | Best revenue and ARPU outcome, especially in light theme |
| C | New white visual treatment | Improved trials, but lost to B on final economics |
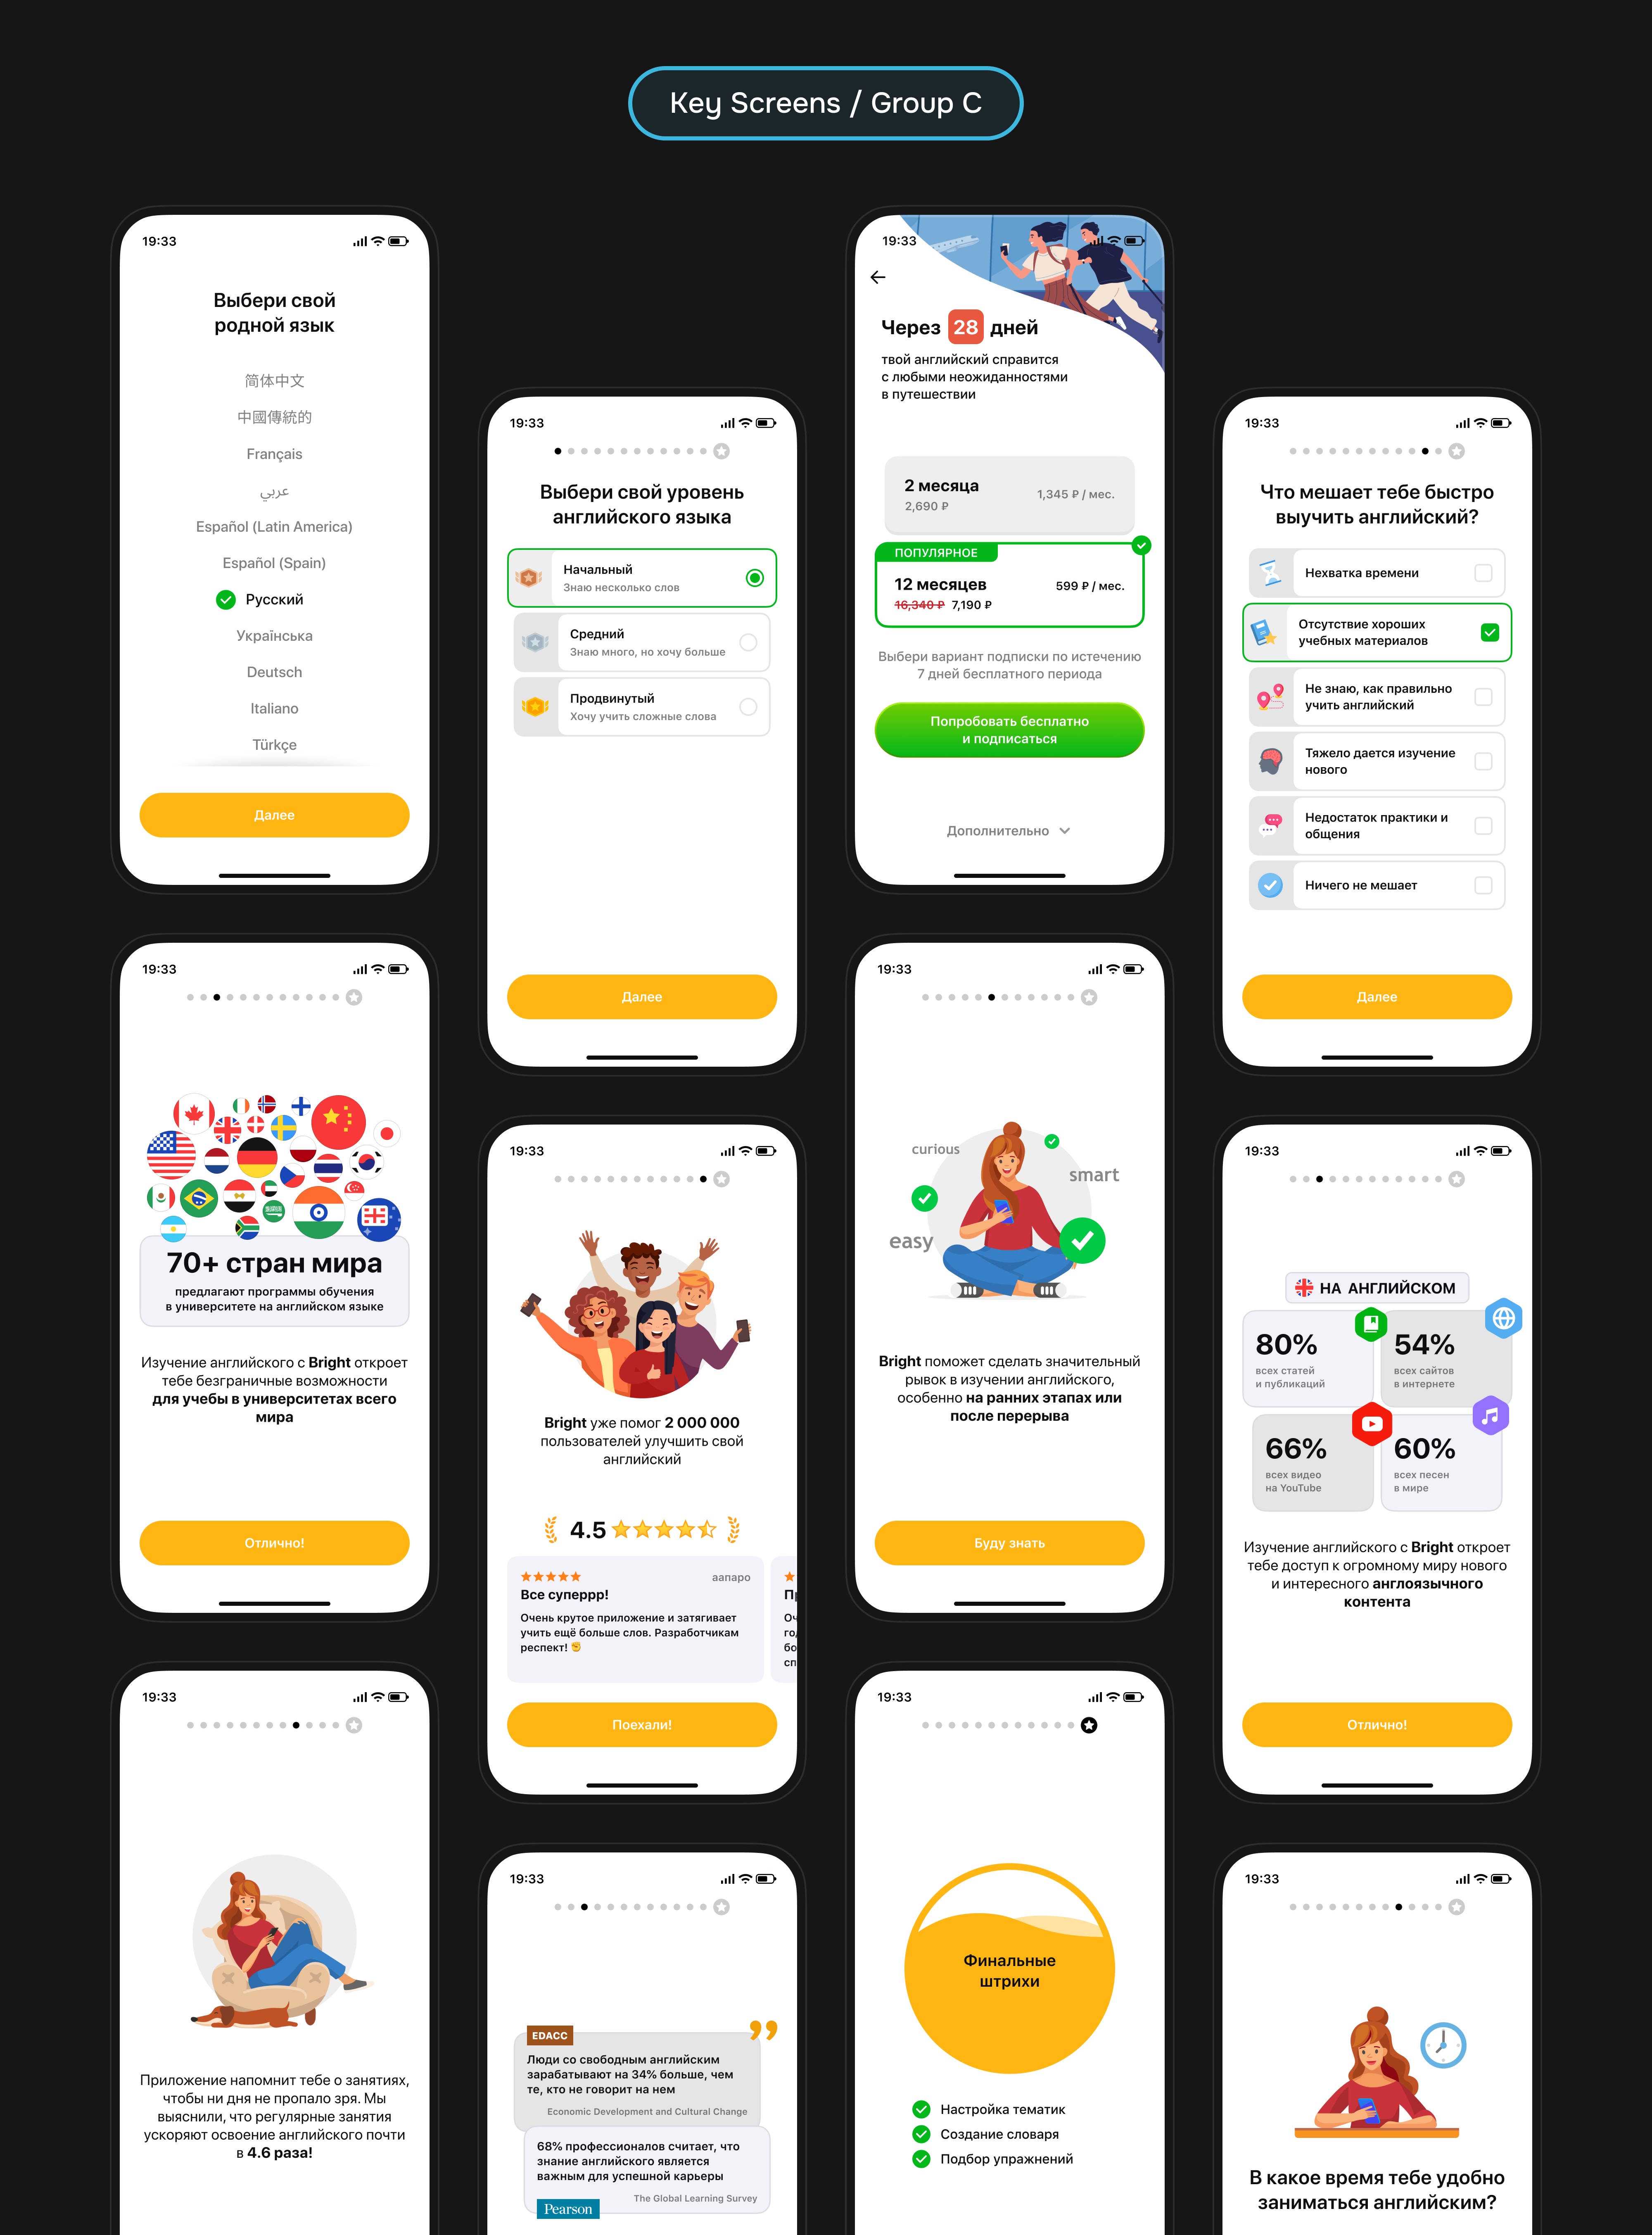
| Slice | Result |
|---|---|
| ARPU per trial | In group B it barely changed: $13.23 versus $13.21. In group C it dropped to $12.81, down 3.2%. |
| Trial‑to‑subscription conversion | In group C it dropped to 28.2% versus 29.8% in control group A. |
| Light and dark themes | In light theme, the solar version B performed best: +6.5% trials. In dark theme, the white version C performed better: +6.4%. |
| Lesson completion after day one | B and C were below control: group A — 29.4%, B — 27.8%, C — 28.5%. |
The outcome was not about maximizing the first conversion step, but about balancing the whole funnel. The white version C delivered the strongest install‑to‑trial result overall, but converted trials to subscriptions worse and lowered ARPU per trial. The solar version B was slightly weaker at the start, but preserved trial quality better and delivered the strongest financial result: +3.4% first‑year LTV revenue and +4.4% ARPU per install.
Outcome
The new onboarding became not an introduction screen, but a personalization funnel. It collected user intent, adjusted learning pace, explained value through relevant arguments, and led users to the paywall with a stronger sense that the program had already been built for them.
Feature 5. Haptic Feedback
In this feature, we focused separately on the feel of the interface. Bright had many places where users tap, choose, confirm, and move sliders: onboarding, paywall, home screen, training cards, topics, and settings. The task was to make those actions feel physically clearer by adding visual feedback and haptics where the finger expects a response.
Hypothesis: if important taps produce short visual and haptic feedback, the app will feel more responsive without changing the core logic.
Effect System
This was a system feature: the point was not to draw separate animations for every screen, but to define a small reusable set of effects. That let the team apply the same pattern to buttons, cells, cards, and sliders, and tune the feel across the app later if needed.
| Effect | Behavior | Where It Was Used |
|---|---|---|
| visual_1 | Element opacity drops to 50% over 0.1s | Language options, survey answers, topics, secondary actions |
| visual_2 | Element scales down to 95% over 0.1s | Primary buttons, paywall products, exercise cards |
| haptic_1 | Light haptic response | Selections, checkboxes, notification slider, topic cells |
| haptic_2 | Heavier haptic response | Primary buttons, paywall, loaders with checkmarks, training cards |
The scope covered onboarding, purchase success, entry testing, paywall and upsells, home screen, extra‑practice cards, topic screens, and topic and level settings. To users it looked like a small detail, but in practice it touched almost the whole first‑session journey.
A/B Test
The A/B test ran in versions 2.7.22‑2.8.0 from October 2 to November 24, 2025. Group A saw the app without the changes; group B saw visual and haptic feedback. Landing‑page users were excluded from the report so the analysis focused on the in‑app effect.
The result was positive. Overall financial metrics improved; at the same time, the feature did not break key learning metrics: day and exercise completion changed only slightly. This is exactly the kind of improvement that should be judged not only by conversion, but also by product feel.
Takeaway: haptic feedback did not change product mechanics, but gave the interface a more physical feel. For a learning app, that matters: users repeat the same actions many times, and each small confirmation makes the rhythm of practice feel better.
Bonus Feature. Dark Theme
This part is a bonus because the dark‑theme A/B test was not a winning story. Quite the opposite: it was a degrading experiment where we disabled dark mode in the control group and kept it in the test group to finally understand whether it hurt metrics and whether it was worth supporting as a full product surface.
The hypothesis was not that dark mode would save everything. It was harsher: if dark mode hurt learning and revenue, we needed to see it, even if the interface looked visually correct.
The A/B test ran in versions 2.6.3‑2.6.5 from August 15 to October 30, 2024. In group A, dark mode was completely unavailable: users always received the light theme. In group B, dark mode followed the standard behavior, with an updated palette, new tokens, and a set of visual fixes.
Why the Test Failed
At the top level, the financial metrics looked misleadingly good: first‑year LTV revenue grew by 3.3%, and ARPU per install grew by 3.6%. But the breakdown showed that almost all of the lift came from light‑theme users who could not see the feature. In the target dark‑theme segment, ARPU per install slightly declined, with a modeled effect of about ‑$600 per month.
The learning metrics were even less pleasant. Users in group B completed the first day less often, completed later days less often, finished new‑word exercises less often, and did fewer exercises overall. The negative effect was spread across the whole journey: there was no single obvious screen that could simply be fixed to save the experiment.
What We Still Learned
Paradoxically, the failure showed that dark mode was not a decorative whim. Around 40% of users reached the paywall in dark mode, and during trial a noticeable share of users switched theme mode in both directions. Some of those switches were automatic, but that still matters for the product: users live in different lighting conditions, times of day, and system settings.
Takeaway: this specific dark‑theme A/B test failed, but supporting dark mode itself proved necessary. Keeping it as a full system surface was not wasted work; changes like this cannot be judged only by mockups or top‑level financial numbers.